
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
Design a self-hosted inference cluster on Kubernetes serving five open models (chat, code, embeddings, reranker, small classifier) with SLOs.
30-second answerSay your answer out loud first, then reveal.
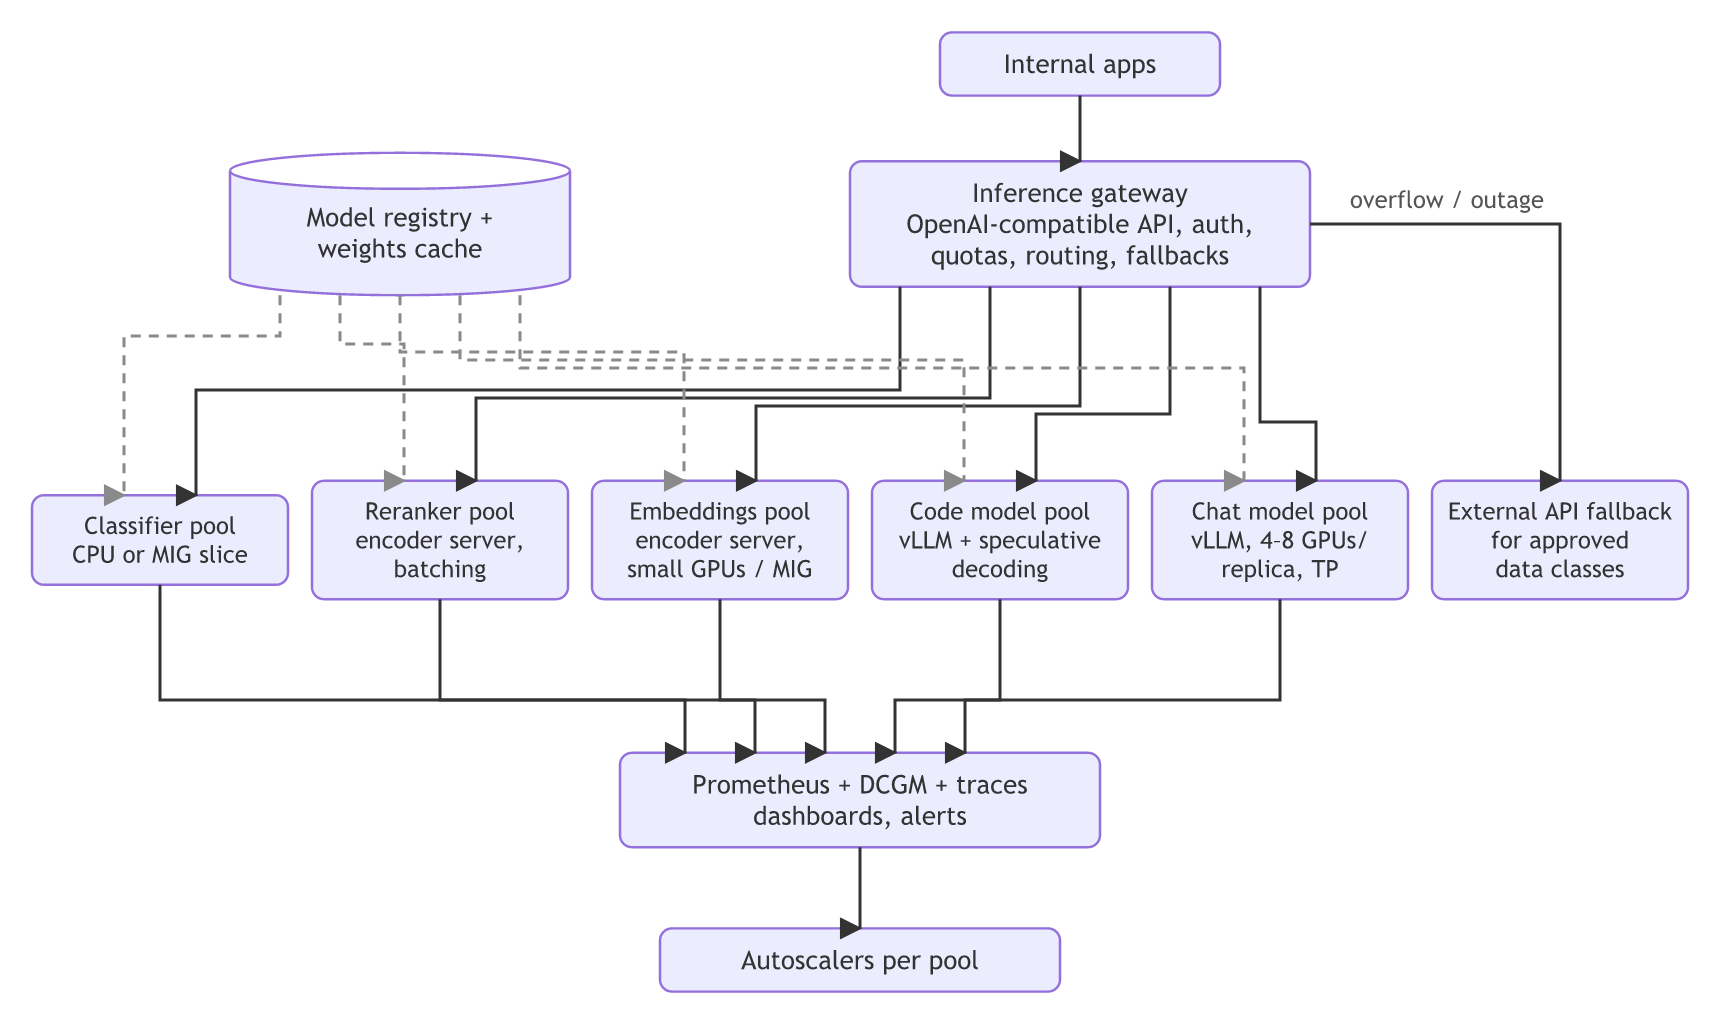
SLO-driven sizing
Examples:
| Model | SLO | Key metric for scaling |
|---|---|---|
| Chat (large) | TTFT p95 < 1.5s, 99.5% availability | Queue depth, KV-cache %, TTFT |
| Code completion (small, fast) | TTFT p95 < 300ms | In-flight requests, TTFT |
| Embeddings | p95 < 100ms for a batch of 32 | Batch queue length |
| Reranker | p95 < 150ms for 50 docs | Queue length |
| Classifier | p95 < 50ms | RPS per replica |
Operational design
- Node pools per GPU type, with taints; a separate pool for batch jobs (spot) that can lend capacity off-peak.
- Release management: blue-green for engine upgrades; canary for model version changes; per-model eval gates.
- Multi-zone replicas with N+1 redundancy for chat and code.
- Security: network policies, mTLS, no internet egress from model pods, signed images and weights.
- Cost reporting: GPU-hours per model and per consuming team.
Related
You understood something today that you didn't yesterday.