
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
Walk through the LLM training lifecycle: pretraining, SFT, and preference alignment.
30-second answerSay your answer out loud first, then reveal.
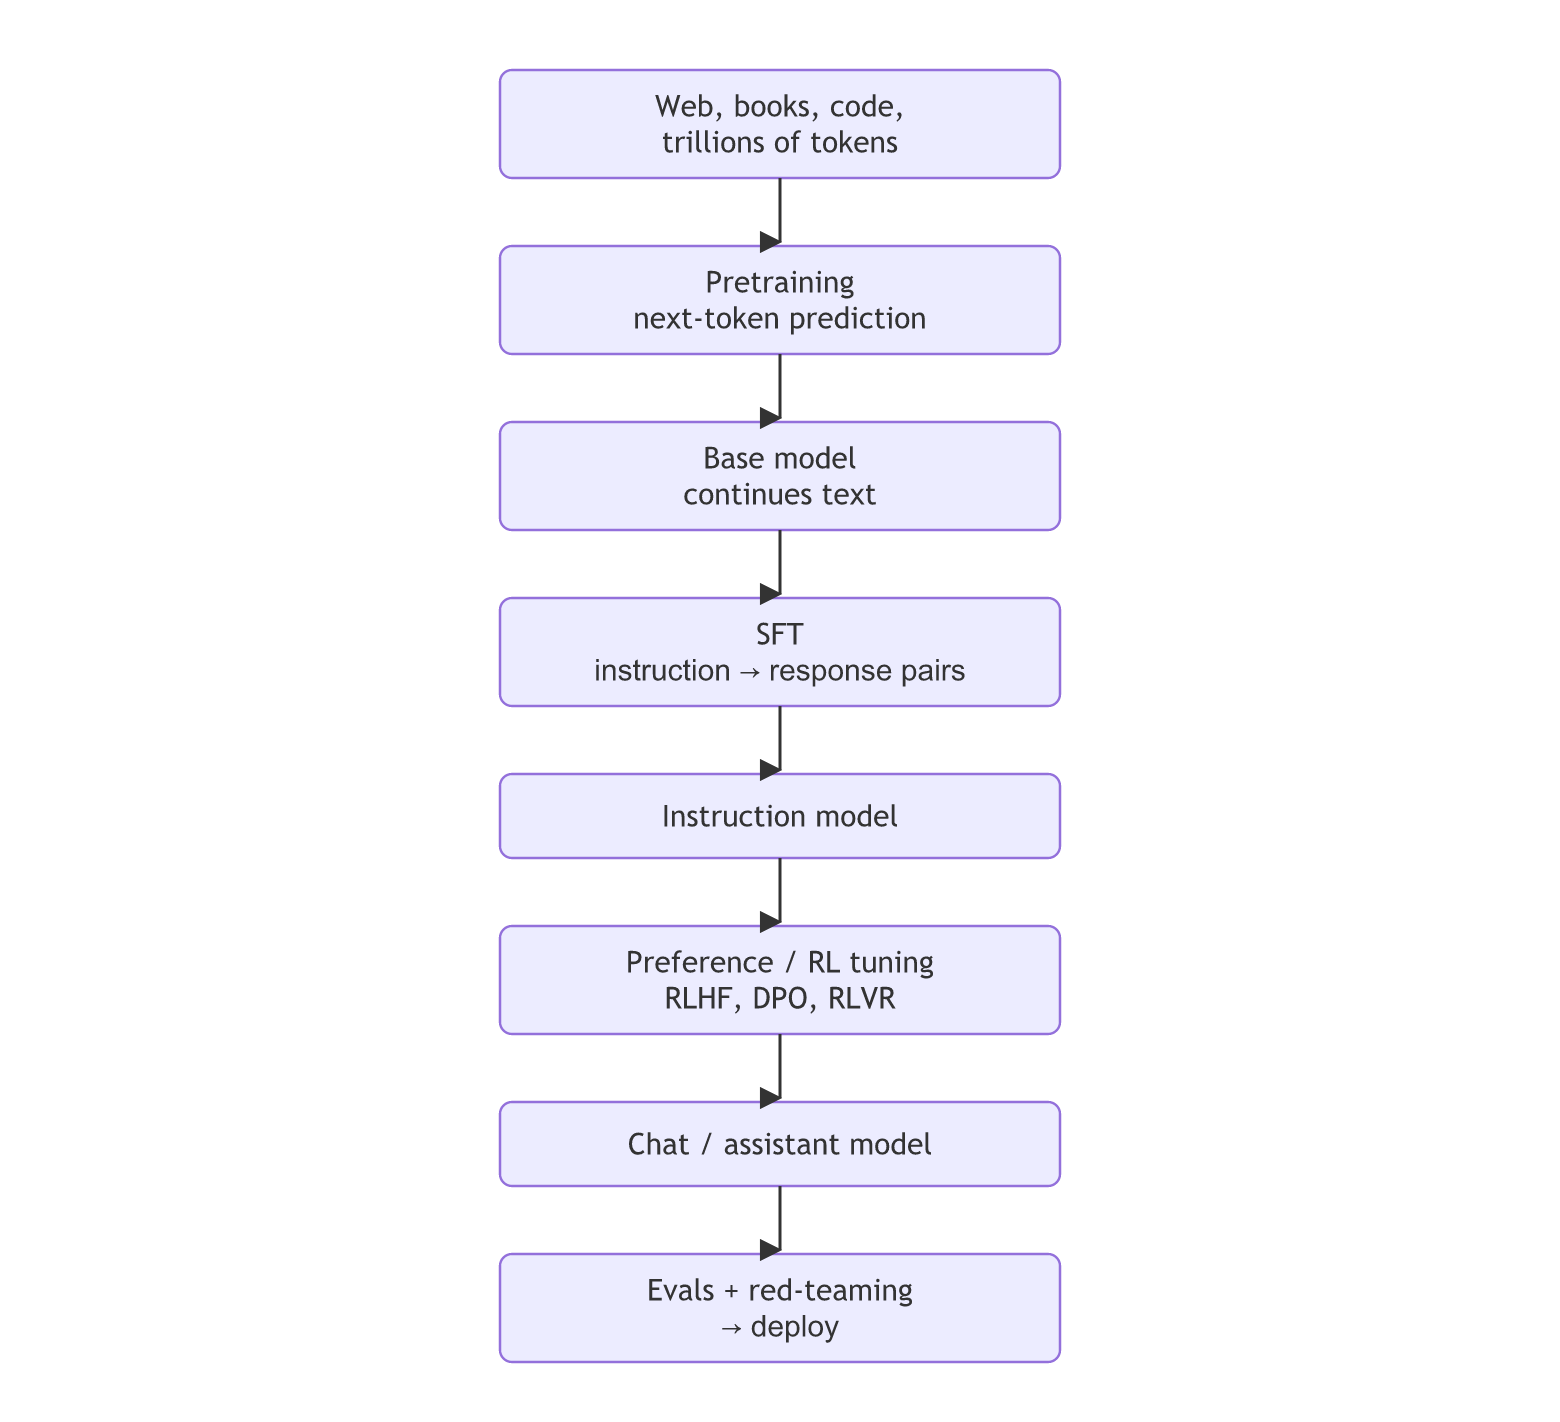
| Stage | Data | Compute | What it adds |
|---|---|---|---|
| Pretraining | Trillions of tokens, mostly unlabelled | Huge (thousands of GPUs for weeks or months) | Language, knowledge, reasoning patterns |
| Mid-training / continued pretraining (optional) | Domain data, long documents, code, maths | Medium | Domain strength, longer context |
| SFT | ~10K–1M high-quality demonstrations | Small | Following instructions, formats, tool use |
| Preference / RL | Comparisons (A better than B), reward models, verifiable tasks | Small–medium | Helpfulness, safety, style, reasoning |
Base vs instruct models: ask a base model "What is the capital of France?" and it may continue with more quiz questions. An instruct model answers.
Follow-ups to expect
- How does RLHF work in detail? (Q24.) What is DPO? (Q25.)
Related
Every expert started right here.