
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
What is multi-head attention? What are Multi-Query Attention (MQA) and Grouped-Query Attention (GQA), and why do modern LLMs use GQA?
30-second answerSay your answer out loud first, then reveal.
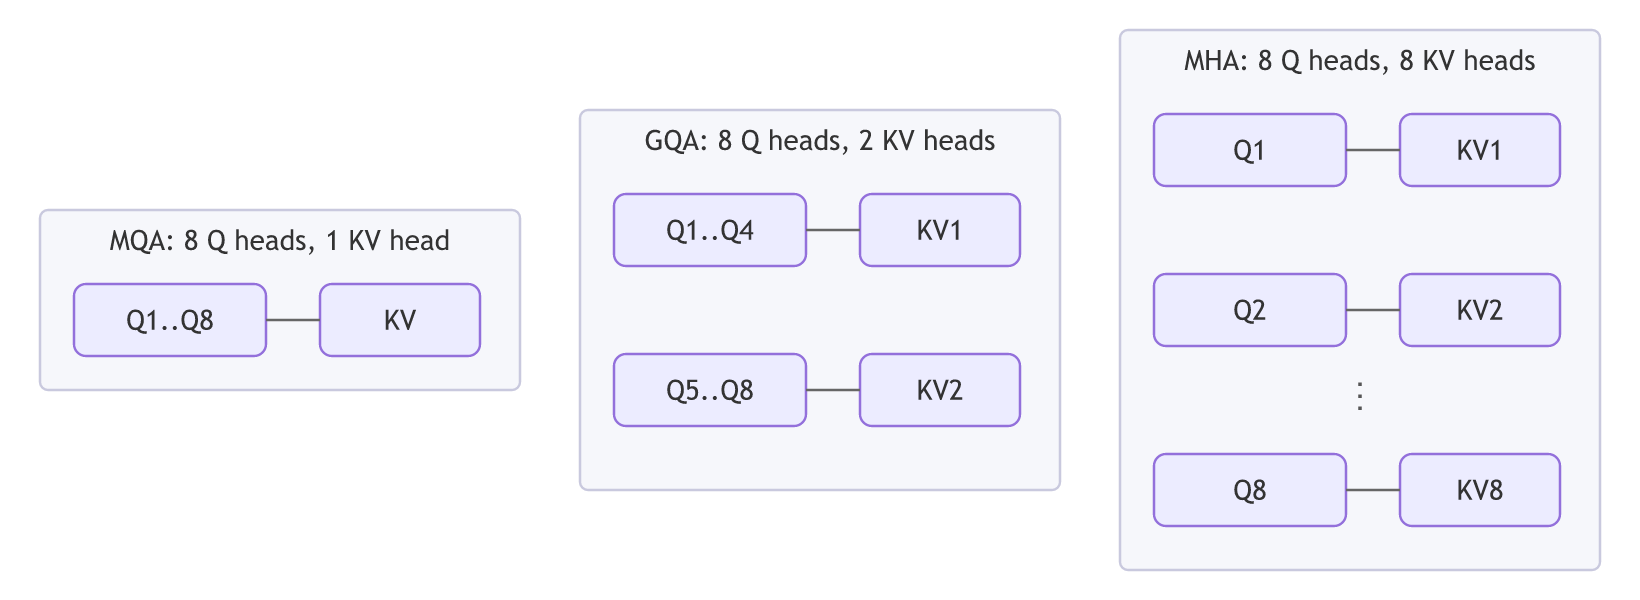
Multi-head mechanics: with d_model = 4096 and 32 heads, each head works in 128 dimensions. Outputs are concatenated (back to 4096) and projected with W_O.
Why KV heads matter: during generation, the KV cache stores K and V for every layer, KV head and past token. Its size scales with the number of KV heads.
| MHA | GQA | MQA | |
|---|---|---|---|
| KV heads | = query heads (e.g. 64) | Groups (e.g. 8) | 1 |
| KV cache size | 1x | ~1/8x | ~1/64x |
| Quality | Baseline | ≈ MHA | Slightly lower |
| Used by | Older models | Llama 2 70B, Llama 3, Mistral, many others | PaLM, Falcon (some) |
Why it matters in production: a smaller KV cache means more concurrent users and longer contexts per GPU, and faster decoding (decoding is memory-bandwidth bound, Q20).
Related idea: Multi-head Latent Attention (MLA, DeepSeek) compresses K/V into a low-rank latent to shrink the cache even further.
Related
You understood something today that you didn't yesterday.