
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
How do you build multimodal RAG over documents with images, charts, and scanned pages?
30-second answerSay your answer out loud first, then reveal.
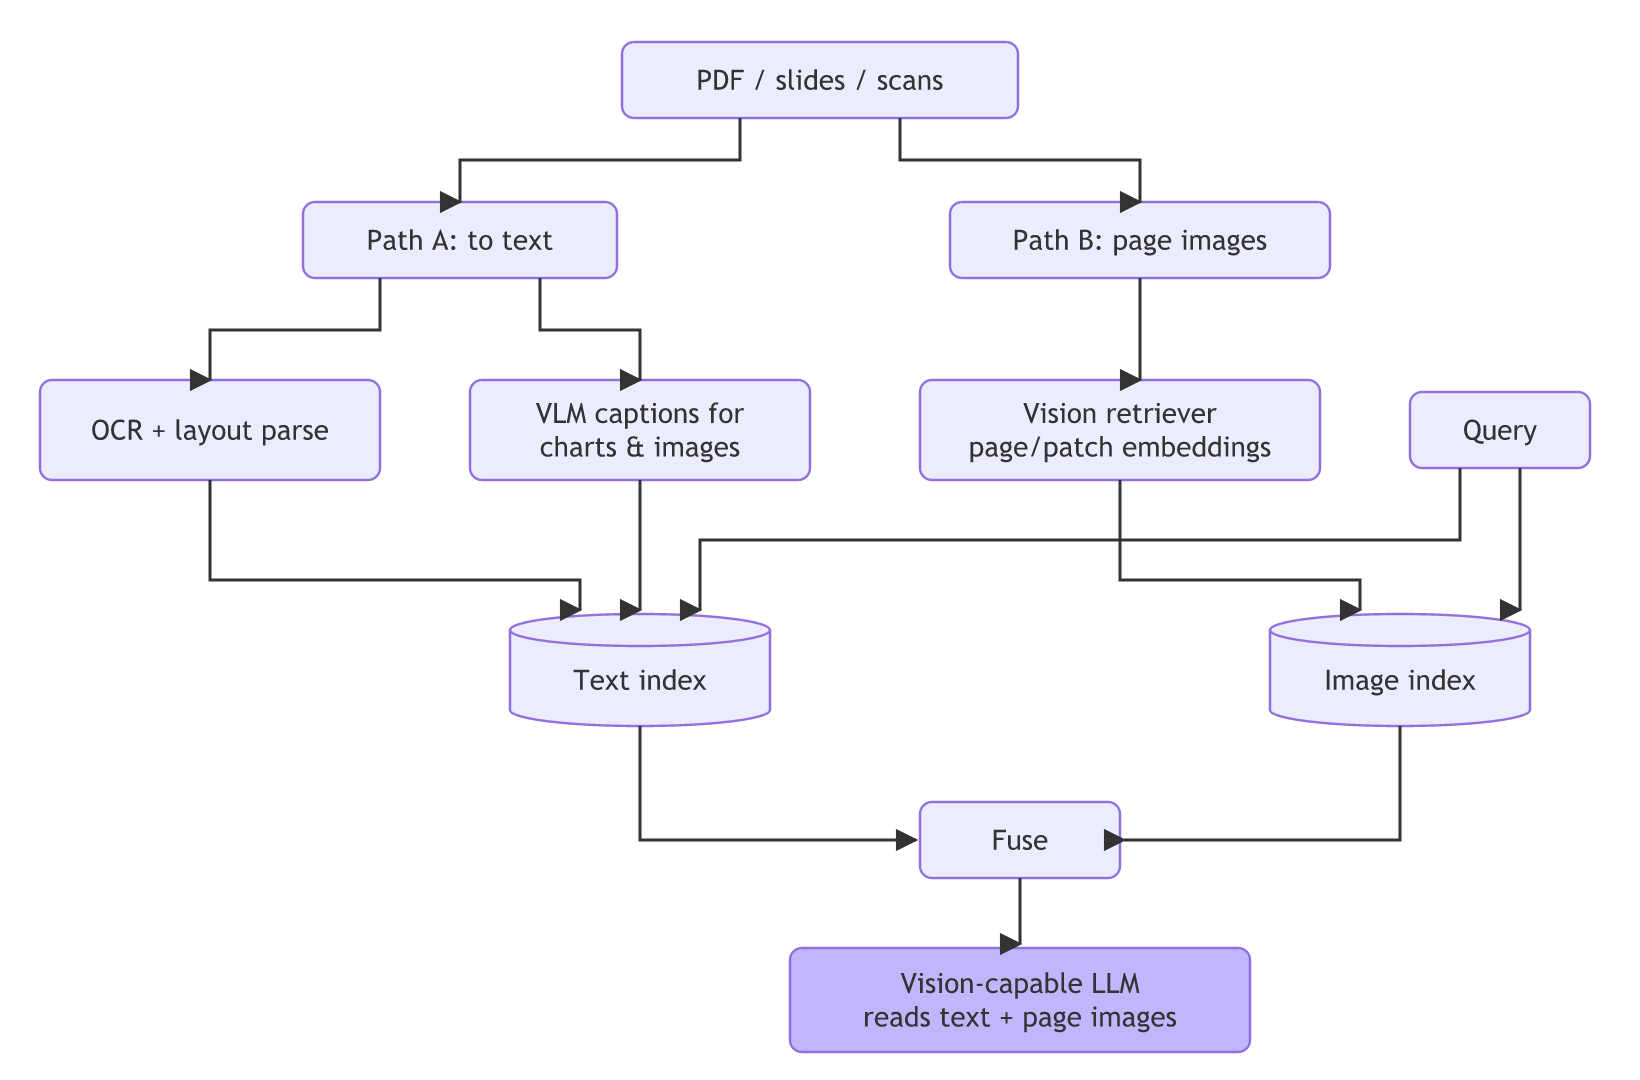
Path A: text conversion
- Pros: reuses your text RAG stack; cheap retrieval; easy citations.
- Cons: captions lose detail; complex charts and diagrams are hard to describe fully; a parsing pipeline per format.
Path B: visual retrieval
- Pros: no fragile parsing; preserves layout, charts and visual tables; strong on visually rich documents (slides, reports).
- Cons: larger indexes (multi-vector); a VLM is needed for generation (higher cost); harder to highlight exact text spans.
Practical design
- Store page number + bounding boxes for citations ("see page 14, figure 3").
- Use the VLM only for pages that matter (top 3–5 page images).
- Evaluate with questions whose answers live in charts or tables, not just in text.
Related
This is what real progress feels like.