
What is reranking? Explain bi-encoders vs cross-encoders.
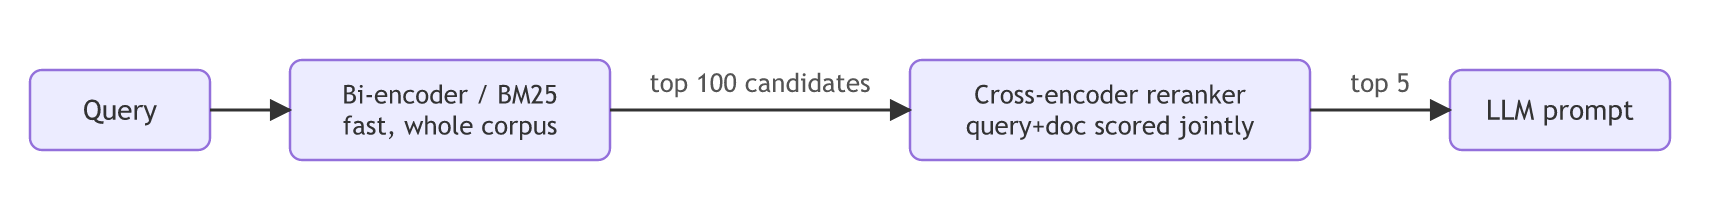
Why cross-encoders are more accurate: attention runs across query and document tokens together, so the model can check whether the passage actually answers the question, not just whether it's on the same topic.
Why they're slow: one model pass per (query, document) pair at query time, and nothing can be pre-computed. Fine for 100 candidates, impossible for 10M.
Options: Cohere Rerank, Voyage rerank, Jina reranker, BGE-reranker (open source), and LLM-based reranking (ask an LLM to score or order passages; flexible but slower and more expensive).
Typical impact: reranking is one of the highest-ROI additions to a RAG pipeline. It often improves precision at the top of the list noticeably, which directly improves answer quality because the LLM sees better context.
Trade-offs: adds roughly 50–300ms latency and per-query cost. Mitigate by limiting the candidate count and using a small reranker.
Follow-ups to expect
- What's ColBERT? A middle ground with late interaction. (See Q33.)
Related
Slow is fine. Stopping is the only problem.