
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
Walk through the two phases of a RAG pipeline: indexing and querying.
30-second answerSay your answer out loud first, then reveal.
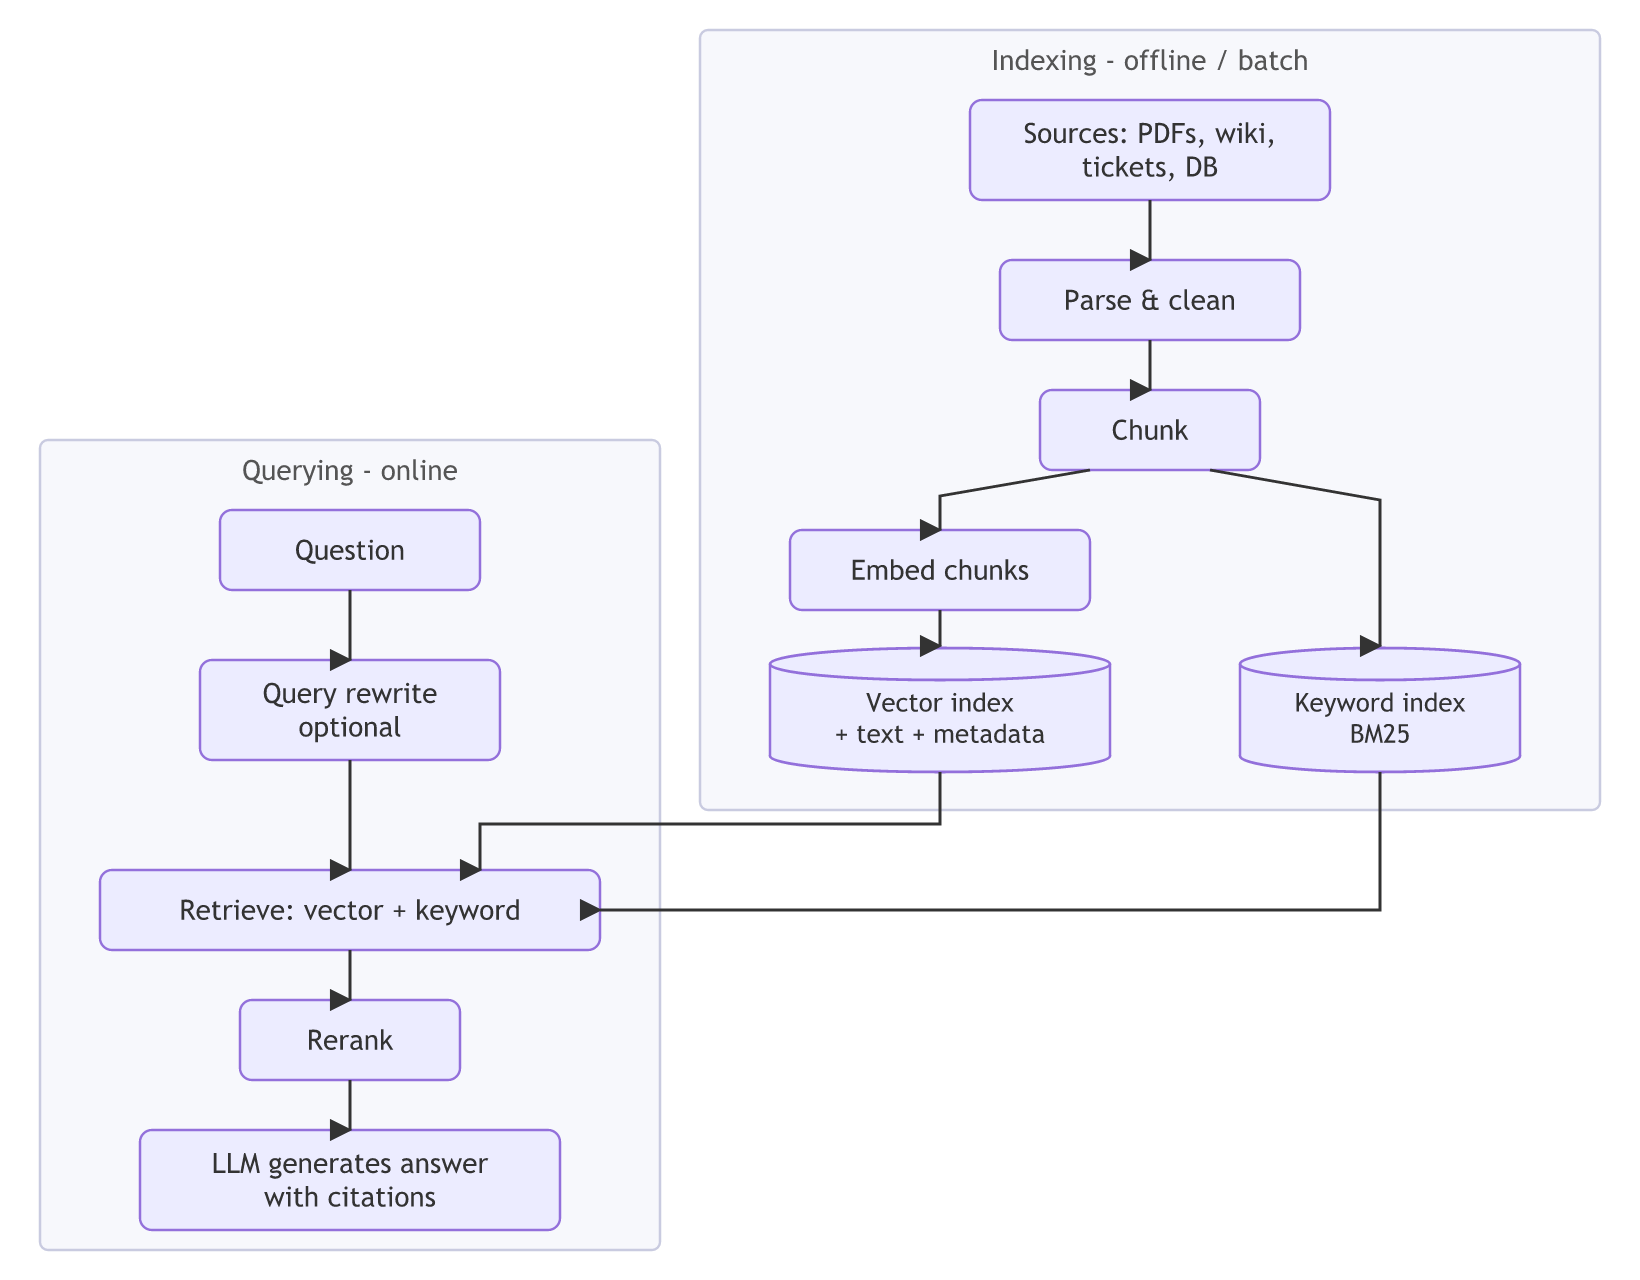
Indexing details
- Loading / parsing: extract text from PDFs, HTML, DOCX, slides; handle tables and images (Q15).
- Cleaning: remove boilerplate (headers, footers, navigation), fix encoding, deduplicate.
- Chunking: split into retrievable units (Q4).
- Enrichment: attach metadata (source, title, date, section, access permissions); optionally add contextual summaries (Q22).
- Embedding + storage: vectors in a vector DB; often also a BM25 index for keyword search.
Querying details
- Query processing: rewrite follow-up questions, expand acronyms, decompose complex questions (Q16).
- Retrieval: dense (vector), sparse (BM25) or hybrid; metadata filters.
- Post-retrieval: rerank, deduplicate, compress, order the chunks.
- Generation: prompt with instructions to answer only from the context and to cite sources.
Interview tip. Most RAG quality problems originate in indexing (bad parsing, bad chunks), not in the LLM. Saying this out loud signals real experience.
Related
You understood something today that you didn't yesterday.