
Design a human review and annotation operation that supports evals at scale (thousands of items per week).
30-second answerSay your answer out loud first, then reveal.
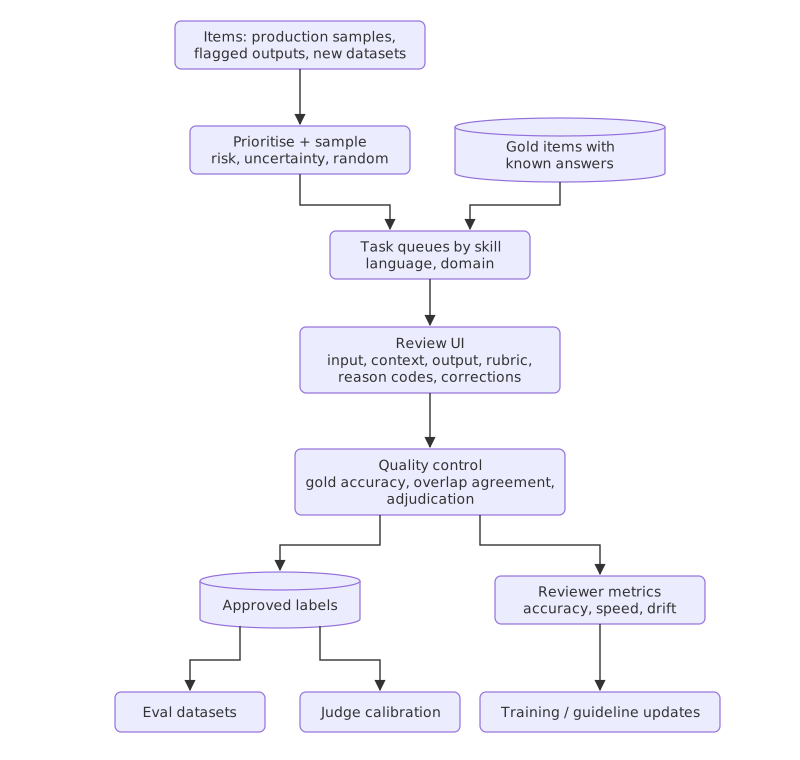
Key elements
- Guidelines: definitions, decision trees, many examples (especially borderline ones), versioned; updated when disagreements reveal ambiguity.
- Reviewer management: qualification tests, ongoing gold-question accuracy, calibration sessions, wellbeing support (for reviewers exposed to harmful content).
- Throughput and cost: estimate minutes per item × volume; for complex items, use LLM pre-labelling with human verification (faster, but watch anchoring bias).
- Agreement metrics: Cohen's / Krippendorff's alpha; disagreement queues to senior adjudicators.
- Privacy: PII redaction where possible, access controls, secure environments, NDAs.
- Closing the loop: label distributions and new failure categories feed back into error analysis and product teams.
Related
Slow is fine. Stopping is the only problem.