
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
What techniques defend against prompt injection? Which ones actually work?
30-second answerSay your answer out loud first, then reveal.
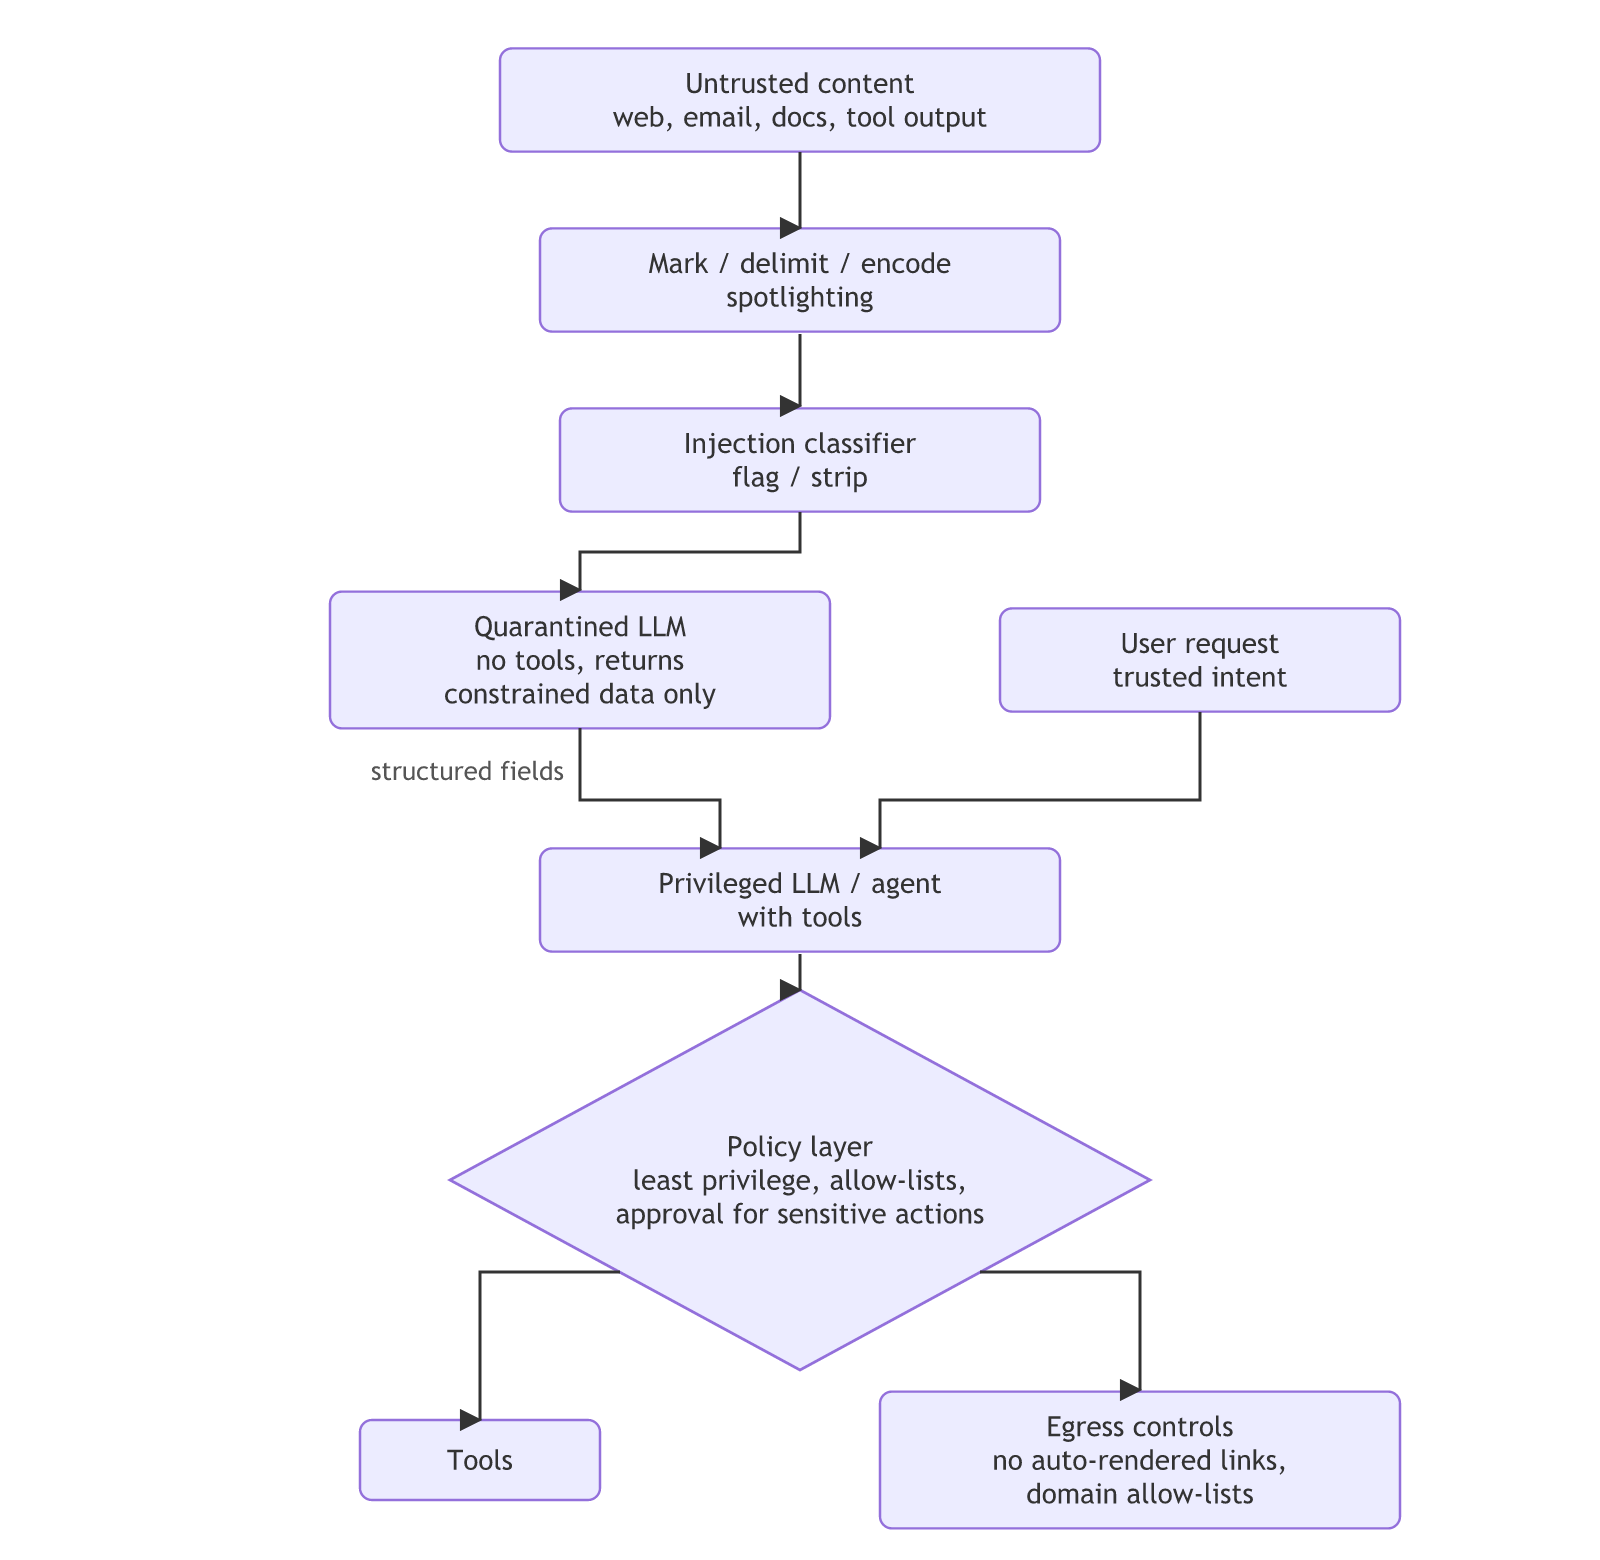
Effectiveness ranking (practical view)
| Defence | Strength | Notes |
|---|---|---|
| Least privilege / no dangerous tools in contexts with untrusted data | Strong | Removes the impact even if injection succeeds |
| Human approval for sensitive actions | Strong | Watch for approval fatigue |
| Dual-LLM / quarantine, capability or data-flow tracking (CaMeL-style) | Strong but complex | Untrusted text never directly drives tool arguments |
| Egress controls (block markdown image exfiltration, URL allow-lists) | Strong for exfiltration | Cheap and important |
| Instruction hierarchy in models | Medium | Models trained to prioritise system > user > tool content |
| Spotlighting / delimiters / "treat as data" | Medium-weak | Reduces success rates; bypassable |
| Injection classifiers | Medium-weak | Useful signal; adversaries adapt |
Key interview line. "I assume injection will sometimes succeed, and design so that a successful injection can't do serious damage."
Related
This is what real progress feels like.