
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
How do you generate useful synthetic test data for evals, and what are the pitfalls?
30-second answerSay your answer out loud first, then reveal.
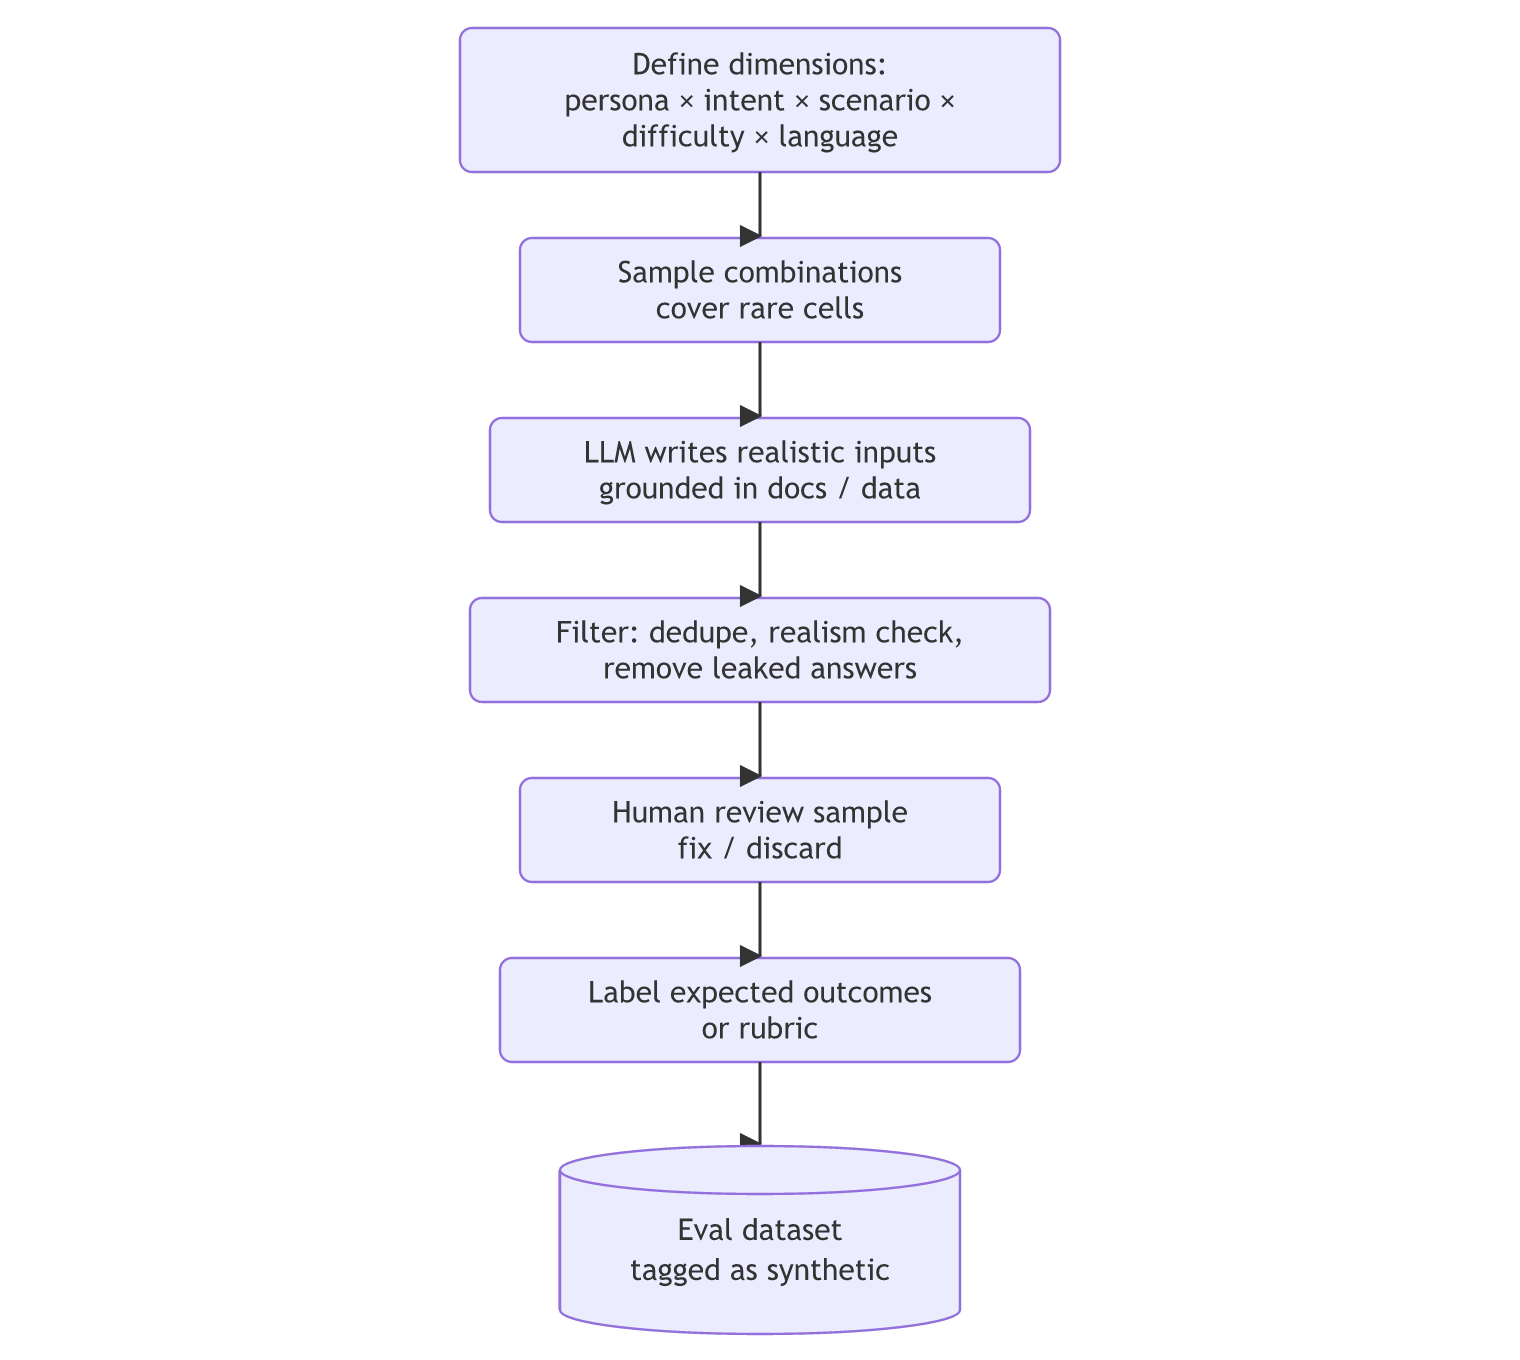
Example dimensions for a banking assistant
- Persona: first-time app user, senior citizen, small business owner, frustrated customer.
- Intent: card block, failed UPI transaction, loan eligibility, KYC update.
- Scenario: missing information, wrong account mentioned, multiple issues at once.
- Language: English, Hindi, Hinglish (typed in Latin script).
Pitfalls
| Pitfall | Mitigation |
|---|---|
| Too clean / too similar to the docs' wording (easy retrieval) | Instruct the generator to paraphrase like real users, with typos and slang; compare with real logs |
| Low diversity (mode collapse) | Sample dimensions explicitly; vary seeds and models; dedupe by embedding |
| Generator bias = model-under-test bias | Use a different model family to generate; human review |
| Wrong expected answers | Expert verification of labels |
| Over-reliance | Keep real data as the backbone; tag synthetic examples to analyse them separately |
Related
Every expert started right here.