
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
Design a ChatGPT-like consumer chat application for 10 million daily active users.
30-second answerSay your answer out loud first, then reveal.
Requirements and estimates
- 10M DAU × ~15 messages/day = 150M messages/day ≈ 1,700 QPS average, ~5K QPS peak.
- ~3K input tokens (with history) + ~500 output tokens per message ≈ 450B input and 75B output tokens/day. Inference is the dominant cost, so routing and caching matter a lot.
- SLAs: TTFT < 1s p95; availability 99.9%.
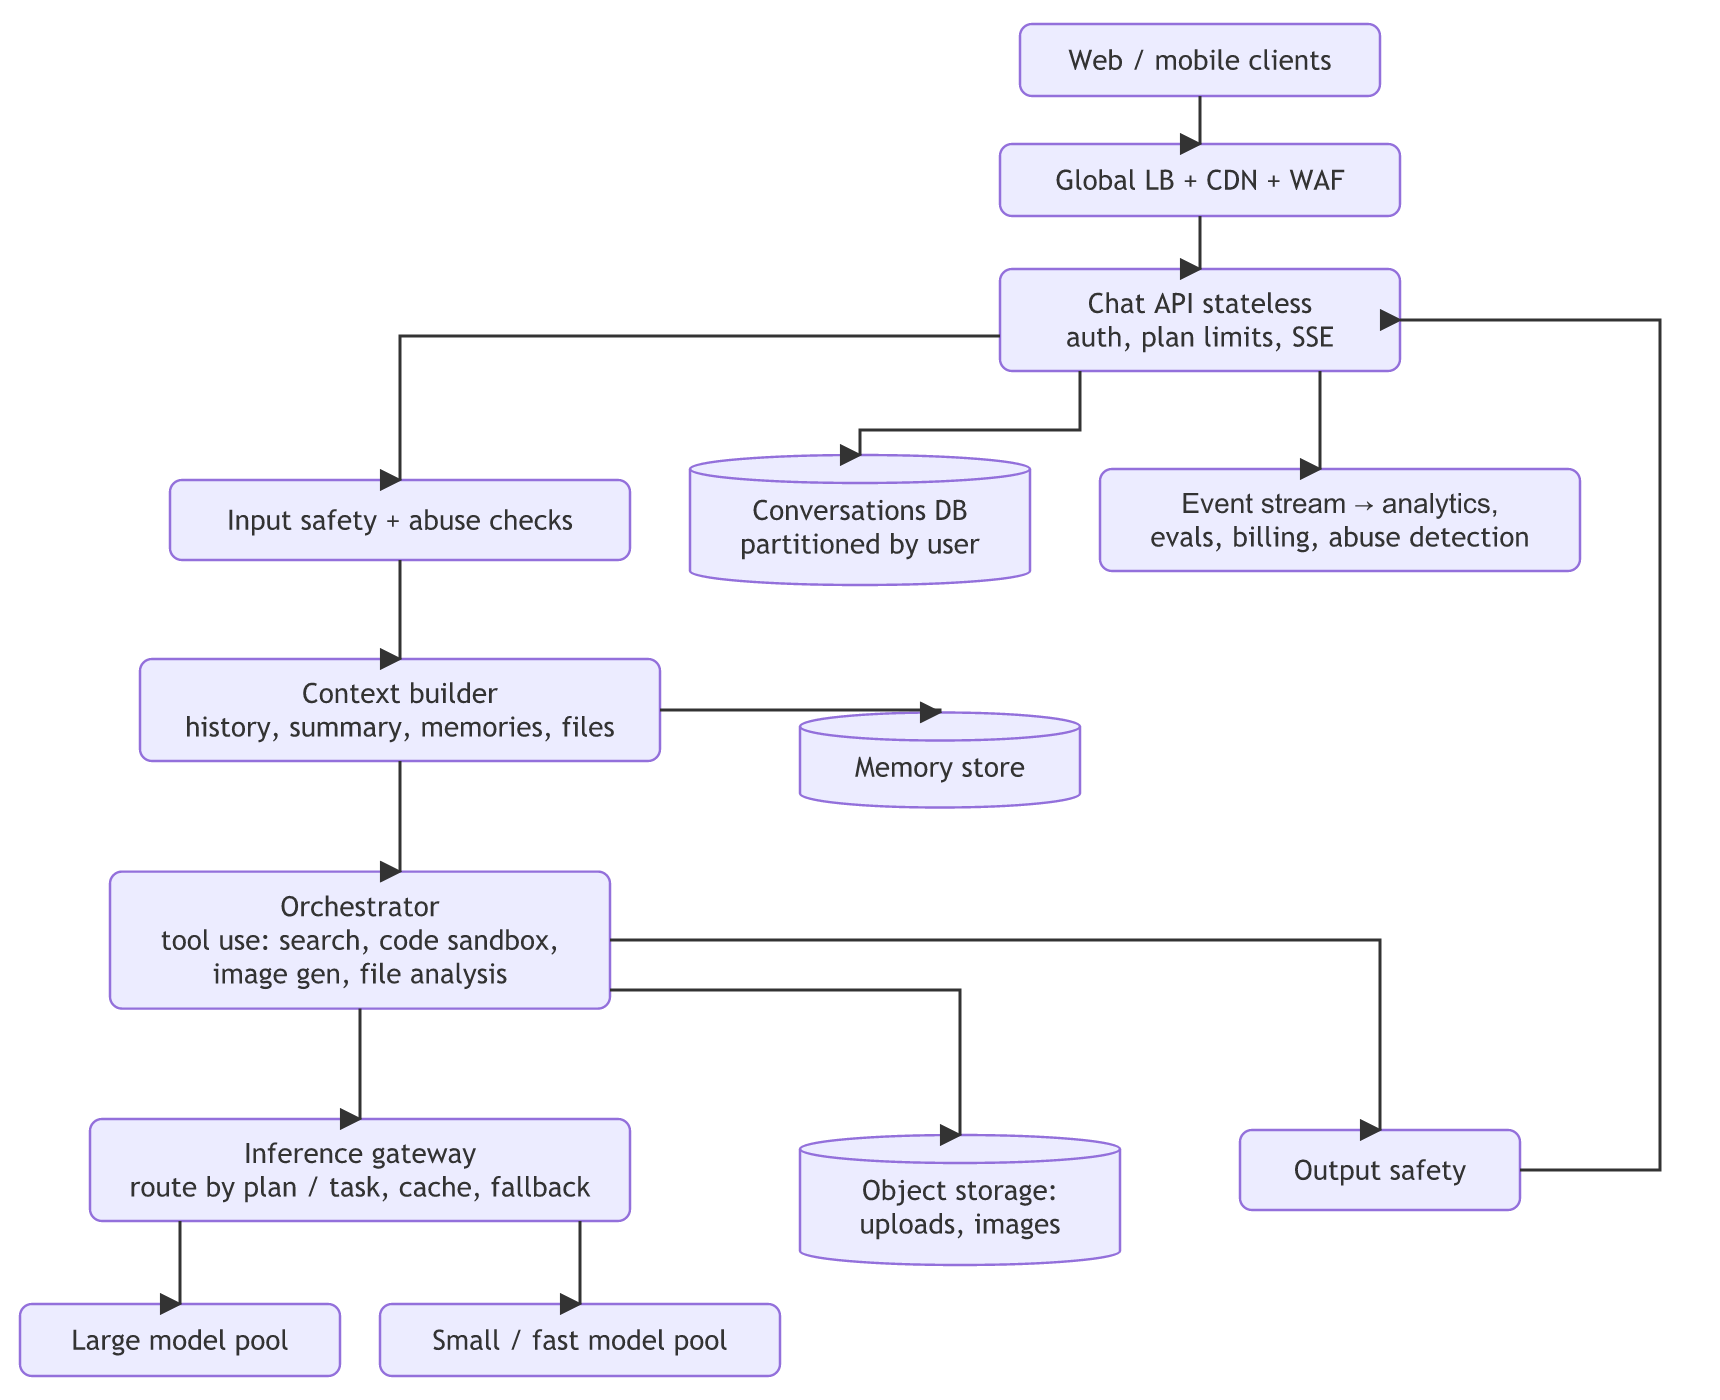
Architecture
Deep dives
- Context building: last N turns + rolling summary + relevant memories; token budget per model; stable prefix for prompt caching (system prompt + tool definitions first).
- Routing: free tier → efficient model; paid → frontier; auto-route by detected task (simple chit-chat vs coding vs reasoning).
- Tools: web search, code execution in isolated sandboxes (gVisor/Firecracker-style), file parsing, image generation as separate async services.
- Storage: conversations in a horizontally scalable DB, sharded by user_id; hot threads cached.
- Rate limiting: per user and plan (messages per window, tokens), plus global capacity-based admission control.
- Safety: layered classifiers, abuse detection on accounts (bot farms, scraping), reporting flows.
- Reliability: multi-region active-active for the API; model pools across regions; graceful degradation to smaller models.
- Cost controls: caching, routing, output length limits, per-plan quotas.
Quality loop
Feedback buttons, sampled evals, A/B testing of model and prompt versions, regression gates.
Related
Little by little, you're building something great.