
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
Design a batch pipeline to classify and tag 50 million product reviews with an LLM.
30-second answerSay your answer out loud first, then reveal.
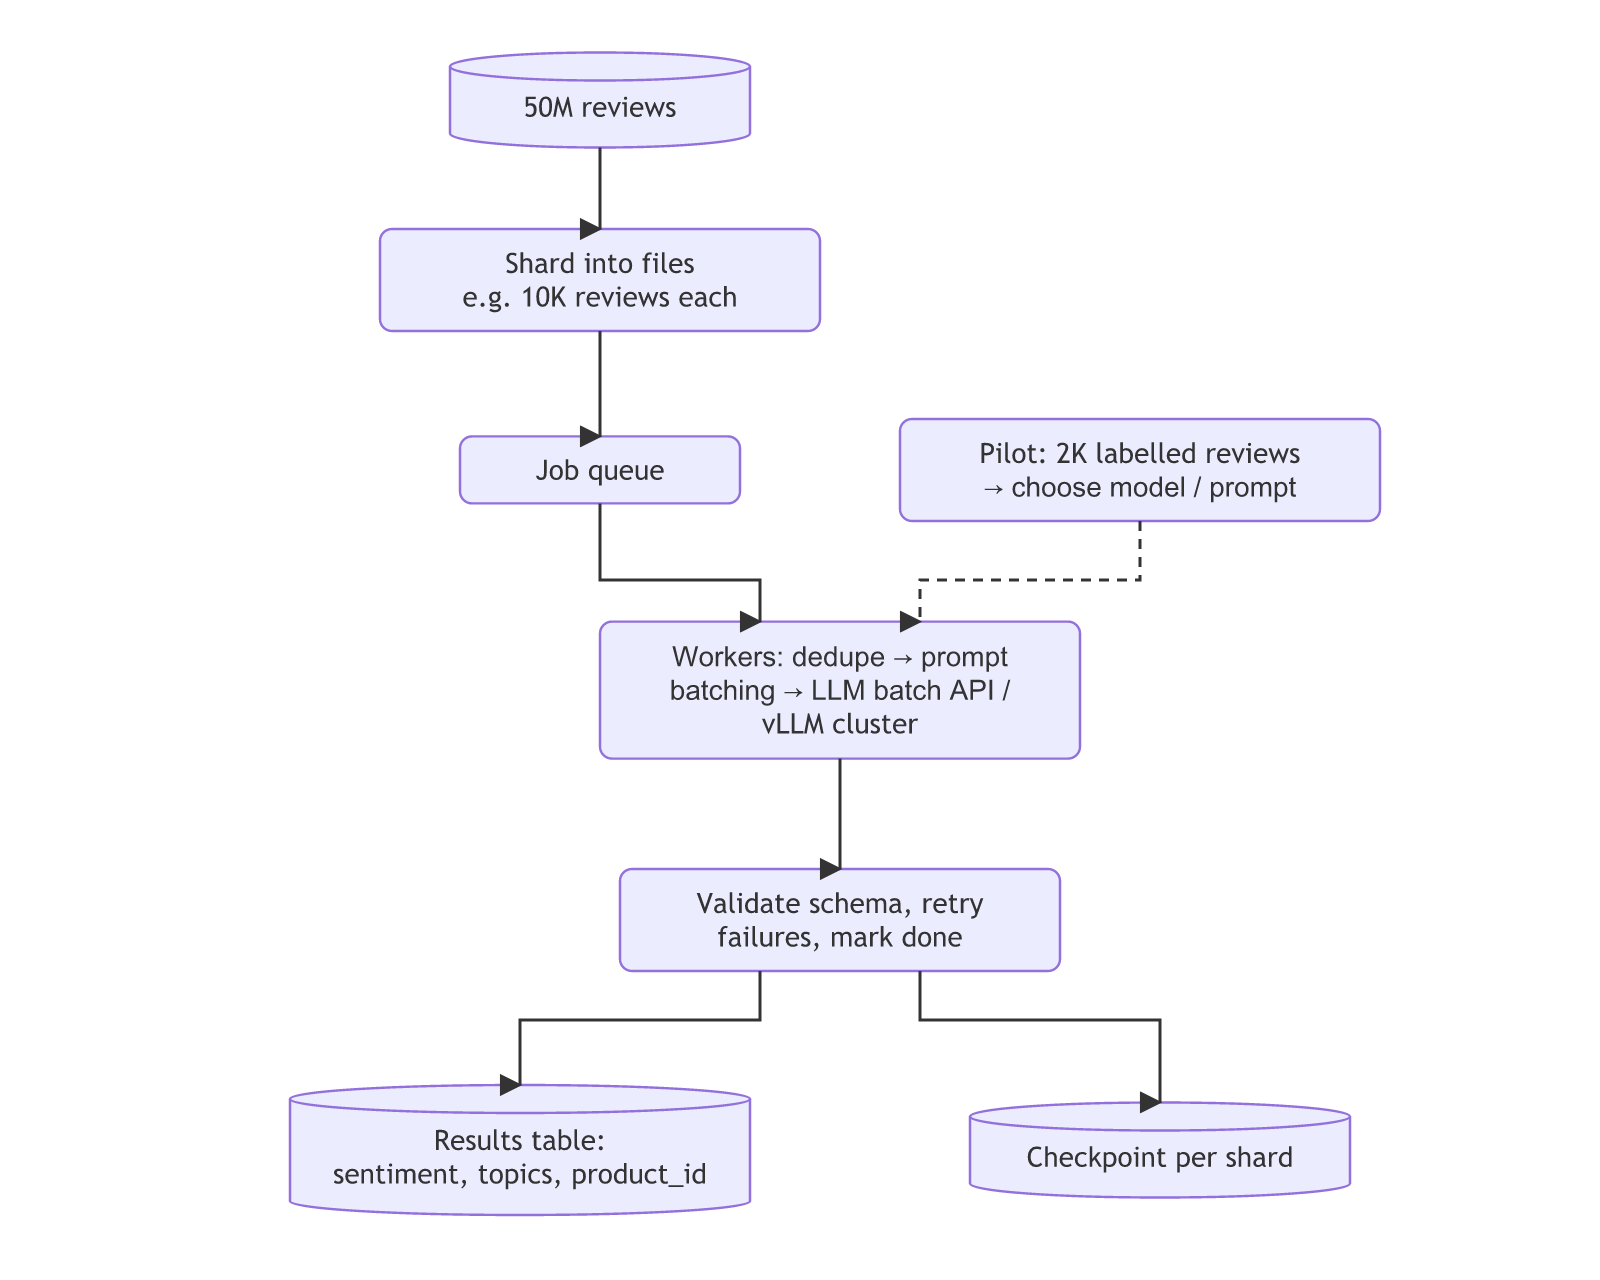
Sizing example
50M reviews × ~150 tokens input + ~100 tokens prompt overhead = 12.5B input tokens
Output ~30 tokens (JSON labels) = 1.5B output tokens
Batch API discounts and a small model make this affordable. A frontier model may be unnecessary for sentiment and topic tags.
Design points
- Pilot first: compare 2–3 models on 1–2K human-labelled reviews; pick by accuracy per dollar.
- Throughput: batch APIs (24h turnaround, cheaper) or self-hosted vLLM with large batches. Respect rate limits.
- Efficiency: deduplicate identical reviews; pack several short reviews per prompt (with IDs) when quality holds; keep outputs tiny.
- Robustness: schema validation, retries with backoff, a dead-letter queue for repeated failures, idempotent writes by review_id.
- Quality monitoring: sample outputs for human audit; track the label distribution against expectations.
- Recurring jobs: if new reviews arrive daily, distil LLM labels into a fine-tuned small model for cheap ongoing inference, and use the LLM only for low-confidence cases.
Related
You understood something today that you didn't yesterday.