
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
How do you implement token streaming for a chat application end to end?
30-second answerSay your answer out loud first, then reveal.
Details that show experience
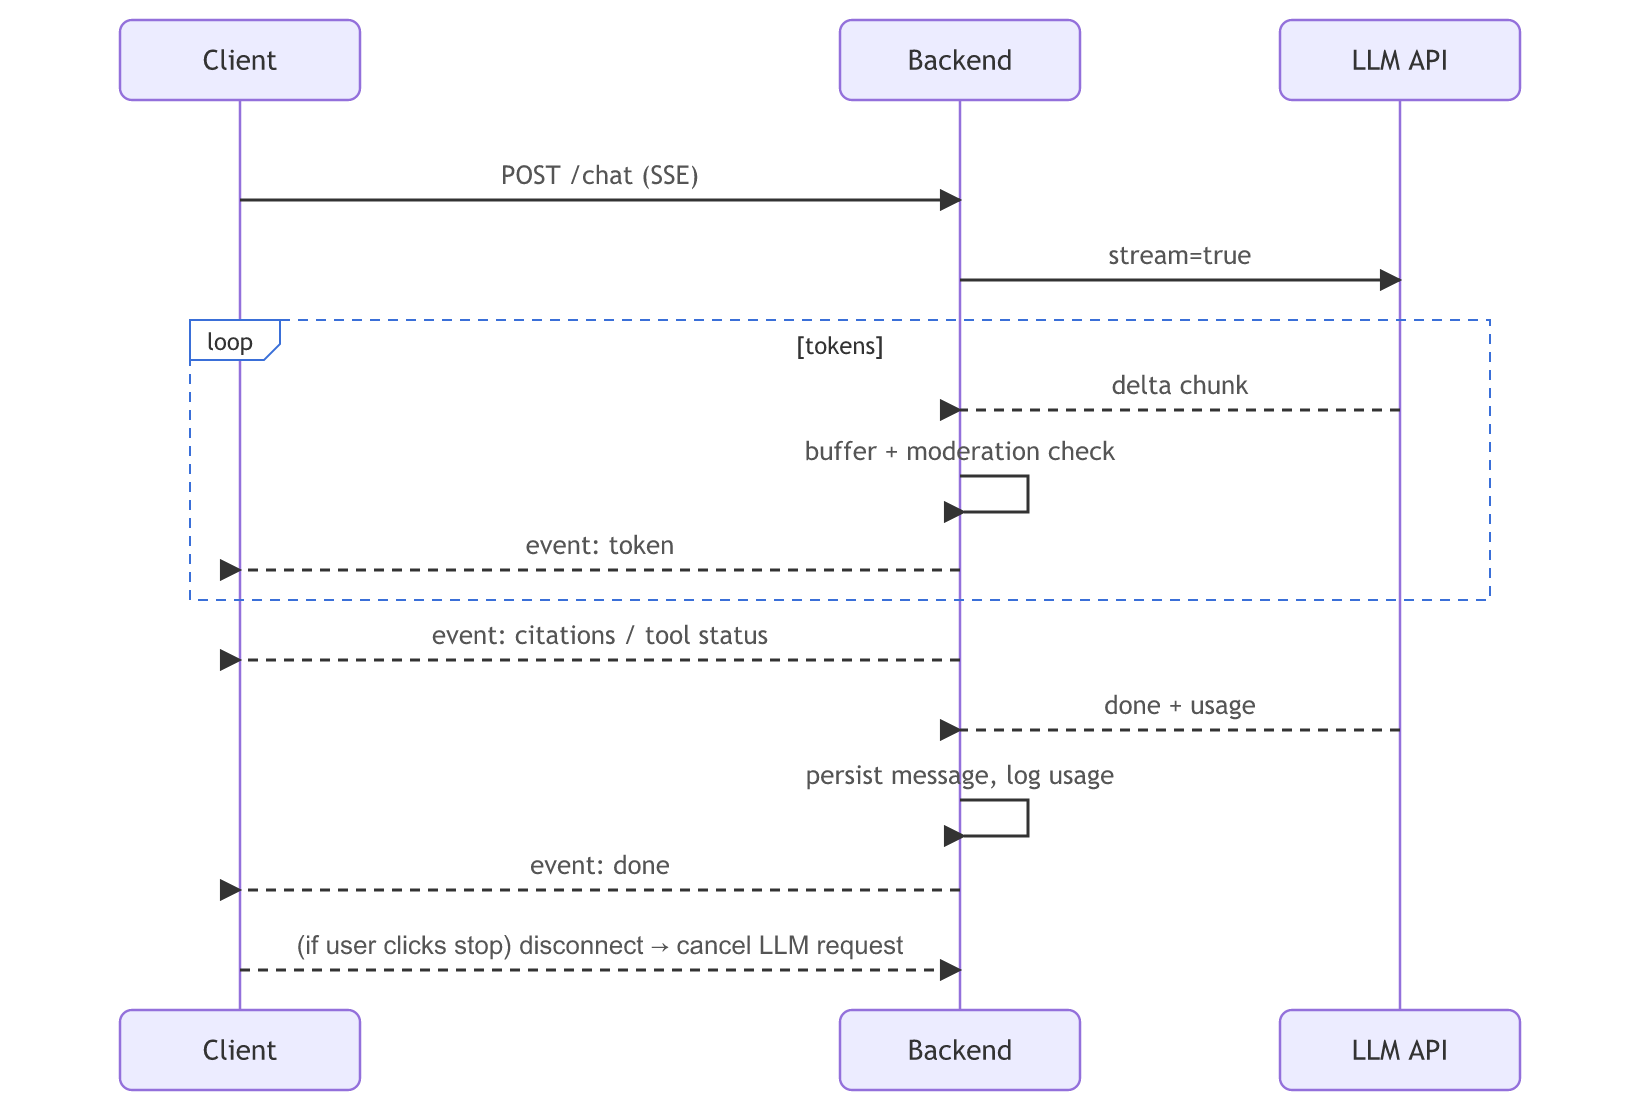
- SSE vs WebSockets: SSE suits server→client token streams and works over HTTP/2 with automatic reconnect. WebSockets suit bidirectional real-time (voice, collaborative editing).
- Infrastructure: disable response buffering (e.g. Nginx
proxy_buffering off), increase idle timeouts, and send heartbeats/keep-alive comments. - Event protocol: typed events (
token,tool_start,tool_result,citation,error,done) so the UI can show progress. - Cancellation: propagate client disconnect to abort the upstream LLM request, which saves tokens.
- Moderation while streaming: buffer a small window or check sentence by sentence; if a violation appears mid-stream, stop and replace the message.
- Persistence: save partial content periodically for long generations, so a resume after reconnect is possible.
- Rendering: incremental Markdown rendering; handle partially streamed code blocks gracefully.
Related
Slow is fine. Stopping is the only problem.