
1
Curious builder0 XP earned · 300 to level 2
0 daysFinish a lesson to begin
Badge collection0 of 6 unlocked
51 small wins to finish your pathNext question →
What kinds of caching can you use in LLM systems?
30-second answerSay your answer out loud first, then reveal.
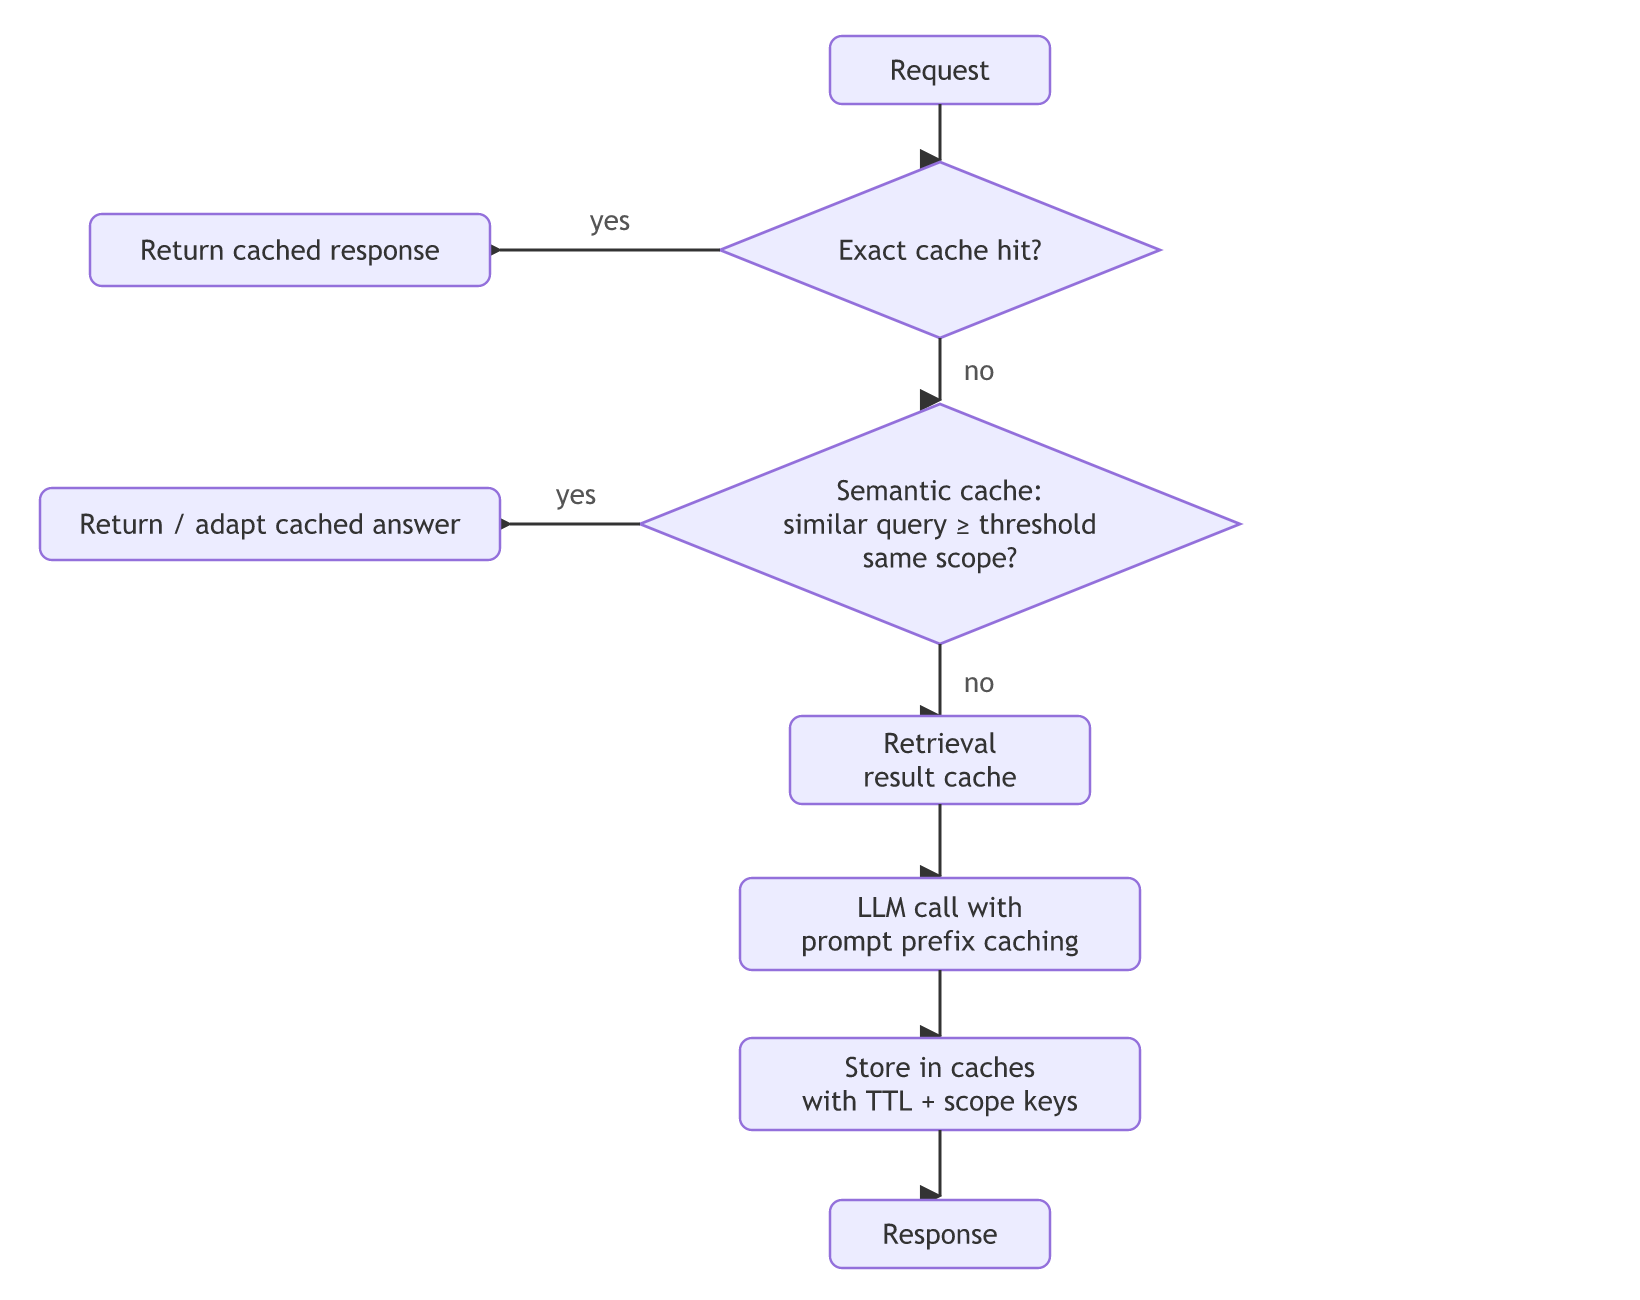
Cache types and their caveats
| Cache | Saves | Risk / caveat |
|---|---|---|
| Exact response | Full LLM call | Low hit rate for free-text; good for FAQs and repeated workflows |
| Semantic | Full LLM call | Wrong answer if "similar" isn't equivalent ("cancel order" vs "cancel subscription"); tune threshold |
| Prompt / prefix (provider or vLLM) | Input token cost + TTFT | Prefix must be byte-identical; put static content first |
| Embedding | Embedding calls | Invalidate when the model changes |
| Retrieval / tool results | DB/API latency | Staleness; TTLs |
Cache key scope (critical): include tenant, user permissions, locale, model version and prompt version. Never serve user A's personalised or permissioned answer to user B.
When not to cache: personalised content, time-sensitive answers ("today's balance"), high-stakes outputs without revalidation.
Related
Little by little, you're building something great.