
LSTM (long short-term memory)
LSTM (long short-term memory) is a recurrent network cell that keeps a separate cell state and uses three gates (forget, input and output) to decide what to erase from it, what to write into it and what to pass on as the hidden state at each step.
Last updated: 07 Oct, 2026 · TensorFlow 2 / Keras · NumPy
Vanishing and exploding gradients in RNNs showed a plain RNN losing the early words of a long sentence. The LSTM keeps a second line of memory that information can travel along for many steps without being squeezed through tanh and Wh at every one.
Keeping context across a long sentence
Take "My name is Krish and my friend name is ___". To fill the blank, the network must keep track of who is being talked about: first the speaker, then the friend. The output depends on words far back, and an RNN, with its short-term memory, cannot hold them.
Now take "Krish likes pizza but my friend likes burger". At "friend" the context switches: the sentence is no longer about the speaker. The network should forget the old subject, focus on the new one, and still be able to refer back to the speaker later if the sentence returns to him. Remembering for a long time, and forgetting deliberately when the context changes, is what the name long short-term memory describes.
Reading the LSTM cell
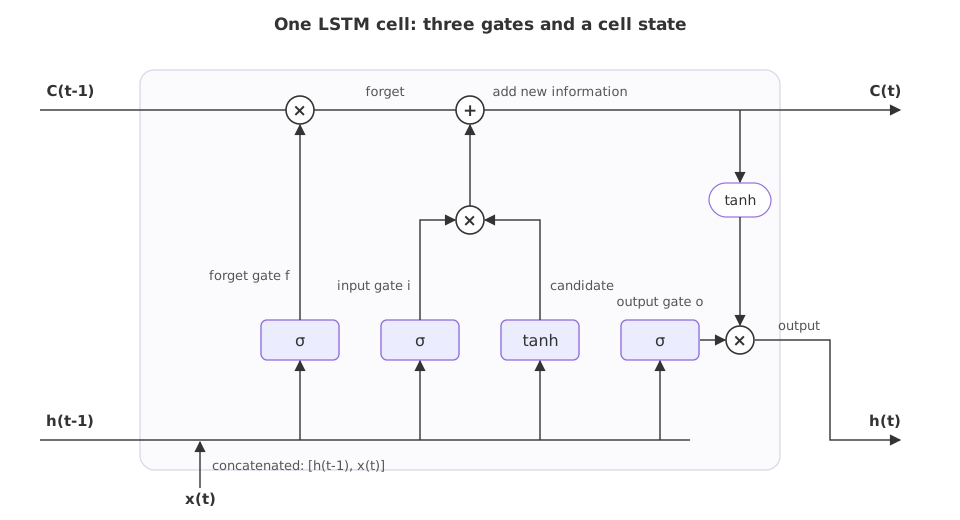
A plain RNN cell has one layer: [ht−1, xt] joined and passed through tanh. The LSTM cell has four interacting layers, three sigmoids and one tanh. The legend of the drawing:
- A σ box is a layer of neurons with a sigmoid activation; its outputs lie between 0 and 1, so it acts as a gate.
- A tanh box is a layer with a tanh activation; its outputs lie between −1 and 1.
- Two lines joining means concatenate; a line splitting means copy.
- A × or + circle is a pointwise operation: elementwise multiplication or addition of two vectors of the same length.
Carrying the cell state like a conveyor belt
The line along the top of the cell is the memory cell, also called the cell state Ct. It works like the conveyor belt at an airport: luggage keeps moving along it, and people can take luggage off or put new luggage on. Along the cell state, the LSTM can remove information and add information, and everything else passes through untouched.
The cell state is the network's long-term memory, because it can carry a value across many steps. The hidden state ht along the bottom is the short-term, working state that the gates read and the next layer receives.
Forgetting with the forget gate
The forget gate decides what to remove from the cell state. The video compares two sentences:
- "Krish likes pizza but he does not like burger": "he" is still the same person, so there is hardly any context switch. The sigmoid gives values near 1, and multiplying the cell state by values near 1 keeps the information.
- "Krish likes pizza but his friend likes burger": when "friend" arrives at xt, the previous context must go. The sigmoid gives values near 0, and the pointwise product turns the old values into zeros: [1, 1, 1, 0, 1] times [0, 0, 0, 0, 0] is all zeros.
Wf has two parts, one block of weights for ht−1 and one for xt, and like every LSTM weight it is shared by all the time steps. The gate is learned from data: it is not a similarity score, and it works number by number, so it can clear the dimensions that hold the old subject while keeping others. Keras starts bf at 1 (unit_forget_bias=True), so a new LSTM keeps its memory until training teaches it to forget. The forget gate itself was added to the original 1997 LSTM by Gers, Schmidhuber and Cummins (2000); every LSTM in Keras and PyTorch has it.
Writing new information with the input gate
The second pair of layers decides what to write. A tanh layer proposes candidate values C̃t between −1 and 1, and the input gate it, a sigmoid, chooses how much of each candidate value to let in:
The cell state is then updated in one line: forget part of the old state, add the gated candidate. Both products are elementwise (⊙), one number at a time:
For "his friend" the gates need ft near 0 and it near 1 on the dimensions that describe the subject: the old subject is cleared and the new one written. For "he" they need the opposite, ft near 1 and it near 0, so the cell keeps what it had.
Choosing the output with the output gate
The last sigmoid, the output gate, decides which parts of the cell state to expose. The cell state goes through tanh and is multiplied by ot; the result is the new hidden state, which is both the cell's output and its input at the next step:
Only ht is filtered. Ct itself goes on to the next step as it is.
Walking through "his friend" with numbers
The cell holds [1, 1, 1, 1, 0] about the first subject, and the candidate for the new subject is [−1, −1, 0, 1, 1]. The code applies both gate settings to the same values.
import numpy as np

C_prev = np.array([1, 1, 1, 1, 0])          # what the cell holds about the first subject
C_tilde = np.array([-1, -1, 0, 1, 1])       # candidate values for a new subject
cases = {"he (same subject)": (np.full(5, 0.98), np.full(5, 0.02)),
         "his friend (new subject)": (np.full(5, 0.02), np.full(5, 0.98))}
for name, (f, i) in cases.items():
    C = f * C_prev + i * C_tilde
    print(f"{name}:")
print(" f*C(t-1) =", np.round(f * C_prev, 2), " i*C~ =", np.round(i * C_tilde, 2), " C(t) =", np.round(C, 2))he (same subject): f*C(t-1) = [0.98 0.98 0.98 0.98 0. ] i*C~ = [-0.02 -0.02 0. 0.02 0.02] C(t) = [0.96 0.96 0.98 1. 0.02] his friend (new subject): f*C(t-1) = [0.02 0.02 0.02 0.02 0. ] i*C~ = [-0.98 -0.98 0. 0.98 0.98] C(t) = [-0.96 -0.96 0.02 1. 0.98]
- "he": f = 0.98 keeps the old values, i = 0.02 lets in almost nothing, and Ct = [0.96, 0.96, 0.98, 1, 0.02] is the old state.
- "his friend": f = 0.02 clears the old values, i = 0.98 writes the candidate, and Ct = [−0.96, −0.96, 0.02, 1, 0.98] is the new subject.
- Each gate works per number: the products are elementwise, so the result is a vector of the same length, never a single number.
Running one LSTM step in NumPy
The code runs one full LSTM step on random numbers: 4 inputs, 3 hidden units, the four equations in order. It also checks how Ct changes with Ct−1.
The four layers on [h(t-1), x(t)]
v = np.concatenate([h_prev, x_t])         # [h(t-1), x(t)]
f = sigmoid(W_f @ v + b_f)                # forget gate
i = sigmoid(W_i @ v + b_i)                # input gate
C_tilde = np.tanh(W_C @ v + b_C)          # candidate values
o = sigmoid(W_o @ v + b_o)                # output gate
The new cell state and hidden state
C = f * C_prev + i * C_tilde              # new cell state, elementwise
h = o * np.tanh(C) # new hidden stateimport numpy as np
def sigmoid(z):
return 1 / (1 + np.exp(-z))
rng = np.random.default_rng(42)
D, H = 4, 3
x_t = rng.normal(0, 1, D) # the current word's vector
h_prev = rng.normal(0, 0.5, H) # h(t-1), the short-term state
C_prev = rng.normal(0, 1, H) # C(t-1), the cell state
W_f, W_i, W_C, W_o = (rng.normal(0, 0.5, (H, H + D)) for _ in range(4))
b_f, b_i, b_C, b_o = np.ones(H), np.zeros(H), np.zeros(H), np.zeros(H) # forget bias starts at 1
v = np.concatenate([h_prev, x_t]) # [h(t-1), x(t)]
f = sigmoid(W_f @ v + b_f) # forget gate
i = sigmoid(W_i @ v + b_i) # input gate
C_tilde = np.tanh(W_C @ v + b_C) # candidate values
o = sigmoid(W_o @ v + b_o) # output gate
C = f * C_prev + i * C_tilde # new cell state, elementwise
h = o * np.tanh(C) # new hidden state
for name, val in [("f", f), ("i", i), ("C~", C_tilde), ("o", o), ("C(t-1)", C_prev), ("C(t)", C), ("h(t)", h)]:
print(f"{name:7s}", np.round(val, 4))
eps = 1e-6 # nudge C(t-1) and watch C(t)
dC = [((f * (C_prev + eps * np.eye(H)[k]) + i * C_tilde) - C)[k] / eps for k in range(H)]
print("dC(t)/dC(t-1) on each unit:", np.round(dC, 4), " equals f:", np.allclose(dC, f))
print("100 steps at f = 0.99:", round(0.99 ** 100, 3), " at f = 0.9:", f"{0.9 ** 100:.2e}", " 0.25 ** 100:", f"{0.25 ** 100:.1e}")
print("LSTM parameters, D=300, H=100:", 4 * (100 * (100 + 300) + 100))
print("Keras LSTM(100) on 40-number embeddings:", 4 * (100 * (100 + 40) + 100))f [0.5249 0.869 0.913 ] i [0.3562 0.6867 0.5226] C~ [0.7613 0.401 0.1239] o [0.4194 0.624 0.4521] C(t-1) [-0.3162 -0.0168 -0.853 ] C(t) [ 0.1051 0.2608 -0.714 ] h(t) [ 0.0439 0.1591 -0.2772] dC(t)/dC(t-1) on each unit: [0.5249 0.869 0.913 ] equals f: True 100 steps at f = 0.99: 0.366 at f = 0.9: 2.66e-05 0.25 ** 100: 6.2e-61 LSTM parameters, D=300, H=100: 160400 Keras LSTM(100) on 40-number embeddings: 56400
What the LSTM step shows
- f, i and o lie between 0 and 1 and C̃ between −1 and 1, as sigmoid and tanh guarantee.
- C(t) = f ⊙ C(t−1) + i ⊙ C̃: for the first unit, 0.5249 × (−0.3162) + 0.3562 × 0.7613 ≈ 0.105.
- dC(t)/dC(t−1) equals f on every unit. On the path along the cell state, each step back multiplies the gradient by the forget gate, not by tanh′ and Wh.
- With f = 0.99 for 100 steps the gradient keeps 0.366 of its size; a plain RNN's sigmoid best case, 0.25¹⁰⁰, is 6.2 × 10⁻⁶¹. At f = 0.9 it falls to 2.66 × 10⁻⁵, so the cell state helps only as long as the gates stay open.
- An LSTM layer has four times the weights of an RNN layer: 160,400 for D = 300, H = 100, and 56,400 for the 100 units on 40-number embeddings in the fake news model.
LSTM vs RNN
| RNN | LSTM | |
|---|---|---|
| States | hidden state ht | hidden state ht and cell state Ct |
| Layers inside the cell | one tanh | three sigmoid gates and one tanh |
| Gradient path back in time | through tanh′ and Wh at every step | along the cell state, through ft |
| Parameters, D = 300, H = 100 | 40,100 | 160,400 |
| Long sentences | early words fade | kept as long as the forget gate stays near 1 |
Where you use an LSTM
- Text classification where context spreads over a sentence, such as fake news titles or reviews.
- Tagging and sequence labelling, often in a bidirectional layer.
- Time series forecasting with long seasonal patterns.
Related
- Previous: Vanishing and exploding gradients in RNNs
- Next: GRU (gated recurrent unit)
- Reference: Understanding LSTM Networks, Christopher Olah (2015)
- Set
b_f = np.zeros(H)instead of ones and see how much smaller f becomes. - In the walk-through, set f = 0.02 and i = 0.02 for "his friend": the cell forgets the old subject but writes almost nothing new.
- Print
0.95 ** 100and place it between the f = 0.99 and f = 0.9 results.
This is what real progress feels like.