
Self-attention
Self-attention is an attention mechanism in which every token of a sequence builds a query, a key and a value from the same sequence and replaces its own vector with a weighted sum of all the values, weighted by how well its query matches each key.
Last updated: 07 Oct, 2026 · NumPy
In the Transformer architecture every encoder layer starts with self-attention. This lesson works one through on the video's three-word example, step by step.
Defining query, key and value vectors
Every token gets three vectors, each with its own job:
- Query (Q): the token that is being updated. Its dot product with every key decides how much attention each token gets relative to it.
- Key (K): what each token is matched on. Keys are compared with the query to measure how relevant each token is to the current one.
- Value (V): the information a token hands over. The weighted sum of the values is the output of self-attention, which goes on to the next layer.
The handwritten notes for the video compare it to a YouTube search: the query is the text typed into the search box, the keys are each video's title, tags and description, and the values are the videos that come back.
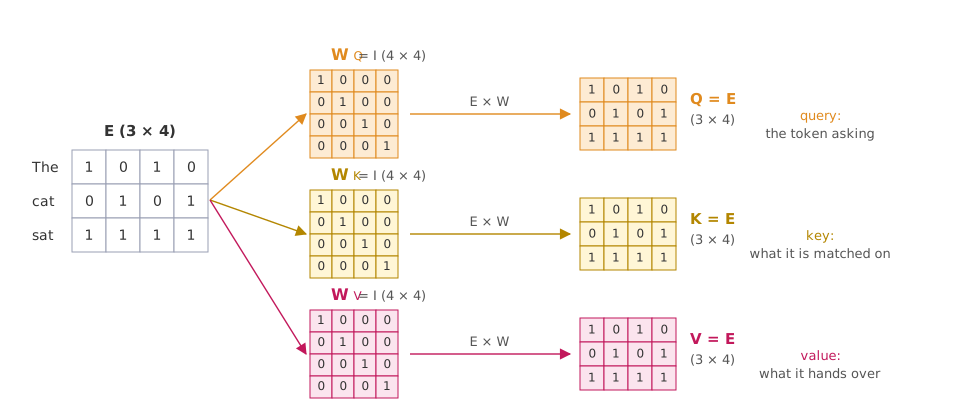
The example: the input sequence is ["The", "cat", "sat"], the embedding size is 4, and the query, key and value vectors have 4 numbers too. Step 1, the token embeddings, gives the fixed vectors EThe = [1, 0, 1, 0], Ecat = [0, 1, 0, 1] and Esat = [1, 1, 1, 1]. Self-attention has to turn each of them into a contextual vector that depends on the whole sentence, and that is what the three roles are for.
Projecting embeddings to Q, K and V
Step 2 is a linear transformation: Q, K and V come from multiplying the embeddings by three learned weight matrices, Q = E WQ, K = E WK and V = E WV. The weights start random and are learned by backpropagation, and the same three matrices serve every position of the sentence. In the example all three are the 4 × 4 identity matrix, so a 1 × 4 embedding times a 4 × 4 matrix gives a 1 × 4 vector, and Q = K = V = E for every token.
Computing the attention scores
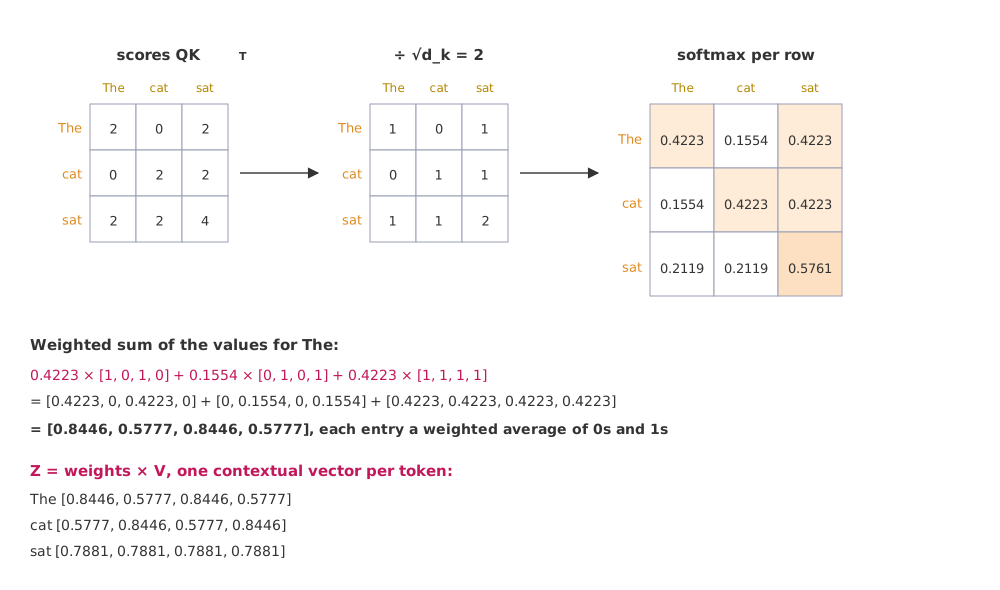
Step 3 computes the attention scores: the dot product of a token's query with the key of every token, its own included. The score says how much attention to give each token relative to the current one. For The:
The same for cat gives 0, 2 and 2, and for sat 2, 2 and 4. As a matrix, the scores are QKT, one row per query.
Scaling the scores and applying softmax
Step 4 divides every score by √dk, the square root of the key size: √4 = 2. The scores of The become [1, 0, 1], those of cat [0, 1, 1] and those of sat [1, 1, 2]. Why the division matters is the subject of Scaled dot-product attention.
Step 5 applies a softmax to each row, so a token's weights are positive and sum to 1:
cat gets softmax([0, 1, 1]) = [0.1554, 0.4223, 0.4223] and sat gets softmax([1, 1, 2]) = [0.2119, 0.2119, 0.5761].
Taking the weighted sum of the values
Step 6 multiplies each value vector by its weight and adds the results. For The:
Column by column, the first entry is 0.4223 × 1 + 0.1554 × 0 + 0.4223 × 1 = 0.8446 and the second is 0.4223 × 0 + 0.1554 × 1 + 0.4223 × 1 = 0.5777. The weights sum to 1, so each entry is a weighted average of the values in its column, and with values of 0 and 1 no entry can go above 1. cat comes out as [0.5777, 0.8446, 0.5777, 0.8446] and sat as [0.7881, 0.7881, 0.7881, 0.7881].
Running self-attention on The cat sat
The projections
W_Q = W_K = W_V = np.eye(4)          # learned in a real model; the identity here
Q, K, V = E @ W_Q, E @ W_K, E @ W_V  # one row per token
Scores, softmax and the weighted sum
scaled = Q @ K.T / np.sqrt(4)                                          # steps 3 and 4
weights = np.exp(scaled) / np.exp(scaled).sum(axis=1, keepdims=True)  # step 5, per row
Z = weights @ V # step 6import numpy as np
tokens = ["The", "cat", "sat"]
E = np.array([[1, 0, 1, 0], # E_The
[0, 1, 0, 1], # E_cat
[1, 1, 1, 1]], float) # E_sat
W_Q = W_K = W_V = np.eye(4) # 4 x 4 identity, as on the board
Q, K, V = E @ W_Q, E @ W_K, E @ W_V # so Q = K = V = E
scores = Q @ K.T # row i: query i against every key
scaled = scores / np.sqrt(4) # d_k = 4, so divide by 2
weights = np.exp(scaled) / np.exp(scaled).sum(axis=1, keepdims=True) # softmax per row
Z = weights @ V # weighted sum of the value vectors
print("scores QK^T:\n", scores)
print("scaled by sqrt(d_k) = 2:\n", scaled)
print("attention weights:\n", np.round(weights, 4))
for t, z in zip(tokens, Z):
print(f"Output({t}) = {np.round(z, 4)}")scores QK^T: [[2. 0. 2.] [0. 2. 2.] [2. 2. 4.]] scaled by sqrt(d_k) = 2: [[1. 0. 1.] [0. 1. 1.] [1. 1. 2.]] attention weights: [[0.4223 0.1554 0.4223] [0.1554 0.4223 0.4223] [0.2119 0.2119 0.5761]] Output(The) = [0.8446 0.5777 0.8446 0.5777] Output(cat) = [0.5777 0.8446 0.5777 0.8446] Output(sat) = [0.7881 0.7881 0.7881 0.7881]
What each row of the output means
- The score matrix [[2, 0, 2], [0, 2, 2], [2, 2, 4]] holds every query against every key in one product.
- Each row of weights sums to 1: The puts 0.4223 on itself and on sat and 0.1554 on cat.
- Output(The) = [0.8446, 0.5777, 0.8446, 0.5777] is the contextual vector that replaces [1, 0, 1, 0].
- sat attends most to itself (0.5761): its vector [1, 1, 1, 1] has the largest dot product with its own key, 4.
Self-attention with learned weights
With identity weights the query and the key of a token are the same vector, so a token always scores itself at least as high as any other token of the same length. Real WQ, WK and WV are three different matrices (512 × 64 each in the paper), learned so that queries and keys pick out useful relations. Random weights with a fixed seed show the difference.
import numpy as np
np.set_printoptions(suppress=True)

E = np.array([[1, 0, 1, 0], [0, 1, 0, 1], [1, 1, 1, 1]], float)   # The, cat, sat
rng = np.random.default_rng(42)
W_Q, W_K, W_V = (rng.normal(0, 0.5, (4, 4)) for _ in range(3))   # three different matrices

Q, K, V = E @ W_Q, E @ W_K, E @ W_V
scaled = Q @ K.T / np.sqrt(4)
weights = np.exp(scaled) / np.exp(scaled).sum(axis=1, keepdims=True)
Z = weights @ V

print("attention weights:\n", np.round(weights, 4))
print("largest weight in each row is at column", weights.argmax(axis=1))
print("Z =\n", np.round(Z, 4))attention weights: [[0.2596 0.2517 0.4886] [0.2833 0.3402 0.3765] [0.2143 0.2496 0.5361]] largest weight in each row is at column [2 2 2] Z = [[ 0.0874 -0.3313 -0.0012 0.8329] [ 0.0772 -0.312 0.0005 0.7623] [ 0.0878 -0.3457 -0.0001 0.8541]]
- All three tokens now attend most to sat (column 2), The and cat included.
- The values are no longer the embeddings, so Z has negative entries: V = E WV can be any vector.
Self-attention vs attention in an RNN encoder-decoder
| Bahdanau or Luong attention | Self-attention | |
|---|---|---|
| Queries come from | the decoder state | the same sequence as the keys |
| Keys and values | the encoder's hidden states | projections of the same tokens |
| Computed | once per output step, in order | for all tokens at once |
| Score | additive or dot product | scaled dot product |
Where you use self-attention
- Every encoder layer of a transformer, where each input token reads the whole input.
- Decoder layers, with a mask, where each token reads only the tokens before it.
- Resolving references: in "The animal didn't cross the street because it was too tired", self-attention lets "it" take in information from "animal".
Related
- Previous: Transformer architecture
- Next: Scaled dot-product attention
- Reference: Jay Alammar, The Illustrated Transformer
- Work out the weights of cat by hand, softmax([0, 1, 1]), and check them against the second row of the output.
- Change Esat to
[1, 1, 0, 0]and see how Output(The) changes. - Remove the
/ np.sqrt(4)and compare the weights of The with [0.4223, 0.1554, 0.4223].
Slow is fine. Stopping is the only problem.