 Machine Learning
Machine learning is a branch of artificial intelligence that learns patterns from data, so a program can predict or decide without hand-written rules for every case.
Last updated: 05 Oct, 2026
Netflix is the example from the video. Watch action movies for a while and the recommendation system suggests more action movies; watch comedies and it suggests comedies. Nobody wrote a rule for you: the system learned the pattern from your viewing history, and it keeps learning as the history grows.
Learning a pattern from data
Every algorithm in this course has the same three pieces:
- Data, a table of rows. The first one in the course is four people's age and weight: 24 and 62, 25 and 63, 21 and 72, 27 and 62.
- A model, a formula with numbers left open, such as the straight line hθ(x) = θ₀ + θ₁x. Training picks those numbers from the data, by making the model's errors on the table as small as possible.
- A prediction, the trained model's answer for a row it has not seen: a new age goes in, a weight comes out. Rows held back from training, the test set, measure how good the answers are.
When the table has an output column to learn, here the weight, the problem is supervised learning: regression when the output is a number, classification when it is a category. When there is no output column and the algorithm finds groups or structure by itself, it is unsupervised learning. Supervised and unsupervised learning covers both.
Listing the algorithms
| Type | Algorithms in this course |
|---|---|
| Supervised: regression and classification | Linear regression, ridge, lasso and ElasticNet, logistic regression, Naive Bayes, K nearest neighbours, decision trees, random forest, AdaBoost, gradient boosting, XGBoost, support vector machines |
| Unsupervised: clustering and dimensionality reduction | K-means, hierarchical clustering, DBSCAN, principal component analysis |
Following the learning path
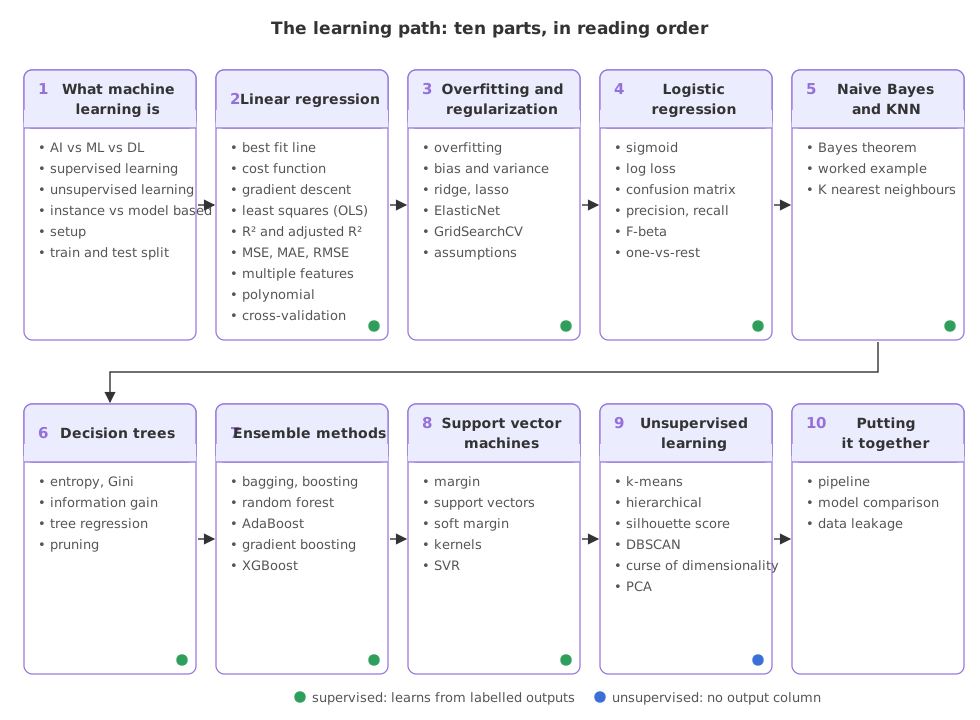
Each part builds on the one before it. Linear regression comes first because its ideas return in every later algorithm: a hypothesis, a cost function, a way to minimise it, and a metric that says how good the result is. The table lists every lesson, part by part.
| Part | Lessons | Starts with |
|---|---|---|
| 1. What machine learning is | AI vs ML vs DL vs data science · Supervised and unsupervised learning · Instance-based vs model-based learning · Installing scikit-learn · Train and test split | AI vs ML vs DL vs data science |
| 2. Linear regression | Simple linear regression · Cost function · Gradient descent · Ordinary least squares · R squared and adjusted R squared · MSE, MAE and RMSE · Multiple linear regression · Polynomial regression · Cross-validation | Simple linear regression |
| 3. Overfitting and regularization | Overfitting and underfitting · Bias and variance · Ridge regression · Lasso regression · ElasticNet regression · Hyperparameter tuning with GridSearchCV · Linear regression assumptions | Overfitting and underfitting |
| 4. Logistic regression and metrics | Logistic regression · Log loss · Confusion matrix · Precision, recall and F-beta · Logistic regression in scikit-learn · One-vs-rest logistic regression | Logistic regression |
| 5. Naive Bayes and KNN | Naive Bayes · Naive Bayes worked example · K nearest neighbours (KNN) | Naive Bayes |
| 6. Decision trees | Decision tree classifier · Entropy and Gini impurity · Information gain · Decision tree regression and pruning · Decision tree in scikit-learn | Decision tree classifier |
| 7. Ensemble methods | Bagging and boosting · Random forest · AdaBoost · Gradient boosting · XGBoost classifier · XGBoost regressor | Bagging and boosting |
| 8. Support vector machines | Support vector machines (SVM) · Support vector regression (SVR) · SVM kernels | Support vector machines (SVM) |
| 9. Unsupervised learning | K-means clustering · Hierarchical clustering · Silhouette score · DBSCAN · Curse of dimensionality · Principal component analysis (PCA) | K-means clustering |
| 10. Putting it together | Machine learning workflow | Machine learning workflow |
Who this course is for
- Beginners who know some Python and want to understand what a model does, not only how to call it.
- Interview preparation. The video's stated aim is to explain each algorithm well enough to clear data science interviews, and its interview questions appear in the lessons, such as "is R squared or adjusted R squared bigger?" and "does linear regression have local minima?".
- Practitioners who have copied scikit-learn code and want the maths behind
fit,scoreand the hyperparameters.
Preparing what you need
- Python basics: variables, lists, functions, loops and importing a library. A first look at pandas helps, since the tables are DataFrames.
- School maths: the straight line y = mx + c, squares, square roots, averages and logs. Derivatives are explained where they appear, in Gradient descent.
- A computer with Python 3.12 or newer (Windows, macOS or Linux), or Google Colab in a browser. Installing scikit-learn walks through both.
- No API keys and no GPU. The datasets ship with scikit-learn, download once, or load from the materials repository by URL.
Following the video and its notes
The lessons follow Complete Machine Learning In 6 Hours (2022, 6 hours 37 minutes), recorded from a week of live sessions. The theory is drawn by hand on a digital board and the practicals run in a Jupyter notebook. PCA comes from a second video, PCA Indepth Geometric And Mathematical Intuition.
The video's description links its materials, which serve as the notes for this course: the Machine Learning folder of The Grand Complete Data Science Materials on GitHub. It holds a PDF of the board notes for every algorithm and the practical notebooks with their saved outputs. The notebooks' CSV files load straight from that repository, and the notes add these topics to the video: Instance-based vs model-based learning, Ordinary least squares, MSE, MAE and RMSE, Polynomial regression and the types of Cross-validation.
scikit-learn has changed since 2022. These are the calls from the video that work differently in the current release:
| The video (2022) | scikit-learn 1.9.1 |
|---|---|
load_boston() | Removed in 1.2; the lessons use fetch_california_housing() |
r2_score(y_pred, y_test) | The order is r2_score(y_true, y_pred); swapping them changes the number |
LogisticRegression(penalty='l1') | penalty is deprecated since 1.8; L1 is l1_ratio=1 with solver='liblinear' or 'saga', because the default solver supports only L2 |
Tree criterion 'mse' | Renamed 'squared_error' |
KMeans default n_init=10 | Default n_init='auto' since 1.4, so cluster scores differ slightly |
Related
- Next: AI vs ML vs DL vs data science
- Then: Installing scikit-learn
- Notes: the Machine Learning materials on GitHub
- Reference: scikit-learn user guide
Every expert started right here.