
Text columns and the str dtype
The str dtype is the storage pandas gives a column of text, so the old test df[col].dtypes == 'O' is False for every text column and the code that splits a table into categorical and numerical features silently splits it the wrong way.
Last updated: 12 Oct, 2026 · pandas 3.0 · scikit-learn 1.9
Copy-on-write and chained assignment was the first of the two changes that break old code without raising. This is the second, and it is harder to spot, because the failure arrives several steps after the line that caused it.
Syntax: the two ways to ask which columns hold text, and which hold numbers.
df.select_dtypes(include='str')        # the text columns as a frame
df.select_dtypes(include='number')     # the numeric columns as a frame

pd.api.types.is_string_dtype(df[col])  # True for one text column
pd.api.types.is_numeric_dtype(df[col]) # True for one numeric column
What a text column is stored as
Up to pandas 2, a column of strings was stored with the dtype object, whose one letter code is 'O'. An object column is an array of pointers to arbitrary Python objects, so a column of names, a column of lists and a column of mixed types all looked identical. pandas 3 gives text its own dtype.
import pandas as pd

AMES = ("https://raw.githubusercontent.com/krishnaik06/"
        "Advanced-House-Price-Prediction-/master/train.csv")
ames = pd.read_csv(AMES)

print("dtype of MSZoning   :", ames['MSZoning'].dtype)
print("holds               :", ames['MSZoning'].unique()[:3].tolist())
print("dtype == 'O'        :", ames['MSZoning'].dtype == 'O')
print("dtype == 'str' :", ames['MSZoning'].dtype == 'str')dtype of MSZoning : str holds : ['RL', 'RM', 'C (all)'] dtype == 'O' : False dtype == 'str' : True
stris the dtype now. The column holds zoning codes,'RL'for low density residential and'RM'for medium density.dtype == 'O'is False. Nothing raised. The comparison is a valid question with a correct answer, and the answer is no.dtype == 'str'is True. The test still works if you change the letter, but a test that has to change with the pandas version is not the one to write.
Splitting a table the wrong way
Almost every older notebook starts a feature engineering pass with two list comprehensions like the ones below: one keeps the columns whose dtype is 'O', the other keeps the rest. They are the lines that decide which columns get encoded and which get scaled. On this 81 column table the first list used to hold 43 columns and the second 38.
categorical = [f for f in ames.columns if ames[f].dtypes == 'O']
numerical = [f for f in ames.columns if ames[f].dtypes != 'O']

print("categorical columns:", len(categorical))
print("numerical columns :", len(numerical), "of", ames.shape[1])categorical columns: 0 numerical columns : 81 of 81
What the two counts mean
- 0 categorical columns. The list is empty, so every encoder, every rare label grouping and every ordinal mapping that loops over it does nothing at all.
- 81 numerical columns. That is the whole table, text columns included. Everything meant for numbers is now pointed at zoning codes, street names and roof styles.
- No error, no warning. Both comprehensions are valid Python and valid pandas. The run continues with two wrong lists.
Where the run finally fails
The failure arrives at the first step that does arithmetic. MinMaxScaler rescales each column into the range 0 to 1, which means it subtracts a minimum and divides by a range, and a zoning code cannot be subtracted.
import pandas as pd
from sklearn.preprocessing import MinMaxScaler

AMES = ("https://raw.githubusercontent.com/krishnaik06/"
        "Advanced-House-Price-Prediction-/master/train.csv")
ames = pd.read_csv(AMES)
numerical = [f for f in ames.columns if ames[f].dtypes != 'O']
print("columns handed to the scaler:", len(numerical))

MinMaxScaler().fit(ames[numerical])columns handed to the scaler: 81
Traceback (most recent call last):
File "main.py", line 10, in <module>
MinMaxScaler().fit(ames[numerical])
ValueError: could not convert string to float: 'RL'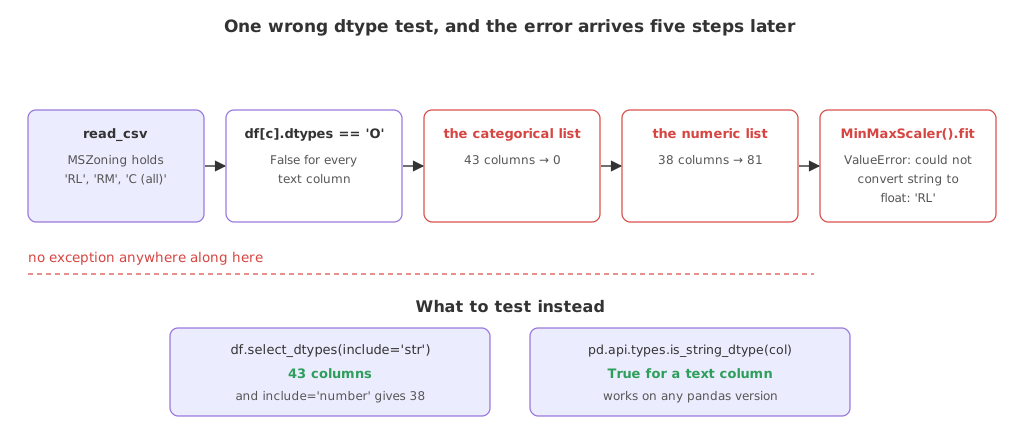
could not convert string to float: 'RL' names a value, not a column and not a line in your own code. Between the dtype test and this traceback there may be thirty cells of imputation and grouping, all of them silently applied to the wrong columns. That distance is what makes this worth a lesson.
Asking the question the right way
select_dtypes selects columns by their type and returns a frame, so .columns.tolist() turns it into the list the loops want. pd.api.types.is_string_dtype answers the same question for a single column and does not care which pandas version is installed, which makes it the safer one inside a comprehension.
categorical = ames.select_dtypes(include='str').columns.tolist()
numerical = ames.select_dtypes(include='number').columns.tolist()
print("select_dtypes      :", len(categorical), "categorical,", len(numerical), "numerical")

is_text = pd.api.types.is_string_dtype
categorical = [c for c in ames.columns if is_text(ames[c])]
numerical = [c for c in ames.columns if pd.api.types.is_numeric_dtype(ames[c])]
print("is_string_dtype    :", len(categorical), "categorical,", len(numerical), "numerical")
print("first four :", categorical[:4])select_dtypes : 43 categorical, 38 numerical is_string_dtype : 43 categorical, 38 numerical first four : ['MSZoning', 'Street', 'Alley', 'LotShape']
- 43 categorical and 38 numerical from both forms, and 43 plus 38 is the 81 columns in the table.
include='str'is the pandas 3 spelling.include='object'still returns the same 43 columns and adds a deprecation warning, so it works today and will not keep working.is_string_dtypeis the version-proof test. It answers True forstrand for the olderobjectcolumns, so the same comprehension runs on either pandas.- A column stored as
categorybehaves differently.select_dtypes(include='str')leaves it out, so passinclude=['str', 'category']when your table has one.is_string_dtypedoes count it, as long as its categories are text.
object vs str vs category
object | str | category | |
|---|---|---|---|
| What it holds | Any Python objects | Text | Text from a fixed set of values |
| When pandas picks it | Mixed types in one column | Every text column, from pandas 3 | Only when you ask for it |
dtype == 'O' | True | False | False |
select_dtypes(include='str') | Included, with a warning | Included | Not included |
is_string_dtype | True | True | True when its categories are text |
| Memory on a repeated column | High | Lower | Lowest |
Where the dtype audit is used
- The first pass over any new table. How many columns hold numbers and how many hold text is the first question in the EDA checklist, and the answer picks the tools for everything after it.
- Building a ColumnTransformer. One list of columns goes to a scaler and another to an encoder, and the lists come from exactly this test.
- Running someone else's notebook. A 2020 notebook that produces empty category lists and a late
ValueErrorhas this cause more often than any other.
len(categorical) straight after the test and check the number against the table's shape.Related
- Previous: Copy-on-write and chained assignment
- Next: Reading a CSV that is not UTF-8
- Reference: Working with text data and DataFrame.select_dtypes
- Run
ames.dtypes.value_counts()and check that thestrcount matches the 43 the fixed test found. - Change
include='str'toinclude='object'and read the deprecation warning pandas prints. - Convert one column with
ames['MSZoning'] = ames['MSZoning'].astype('category')and re-run both tests. Which of the two still counts it?
Every expert started right here.